
Inference
17 pieces on Inference.
News & Analysis
Saaras V4 Covers All 22 Indian Languages With a 3B Hybrid Decoder
Sarvam AI's Saaras V4 handles all 22 scheduled Indian languages plus global English via a 3B hybrid state-space decoder, five output modes, and keyterm prompting at ₹30/hour.
GPT-6 Sol and Luna Cut API Prices 50%—Benchmarks Included
OpenAI's GPT-6 Sol ($2/$10 per 1M tokens) and Luna ($0.10/$0.50) go live in the API with benchmark results against Claude Opus 5 and Fable 5.
NVIDIA PAIR Routes Local AI Requests Across Nodes, Cuts Demo Time 2x
NVIDIA's PAIR beta distributes inference across local GPU nodes via Ollama and LM Studio, showing ~2x faster completion in a three-node demo.
2.4T-Parameter Qwen3.8 Runs on One Node With vLLM and NVFP4
AWS documents a single-node serving path for Qwen3.8-2.4T-A95B on a p6-b300 instance using NVFP4 quantization, cutting TTFT by nearly 60%.
Nvidia PAIR Federates Idle Home Computers Into Local AI Clusters
Nvidia's free, open-source PAIR software links idle home PCs and Macs into a distributed local inference cluster, announced at IFA 2026.
Lily Beats MLX-LM 1.35x on Decode: Perplexity's Rust+Metal Engine for Apple Silicon
Perplexity open-sources Lily, a Rust+Metal inference engine for Qwen3.6-35B-A3B that averages 1.23× prefill and 1.35× decode over MLX-LM on an M5 Max.
Four-Layer Local AI Stack Runs SLMs With No Cloud Dependency
A practical framework for serving, IDE integration, terminal automation, and retrieval — assembling open-weight 1B–14B models into a real development workflow.
Salesforce Gets Multi-AZ HA on SageMaker With SchedulingConfig
Salesforce's 50+ production models needed 2-AZ compliance. SageMaker's new SchedulingConfig parameter closes the gap without surrendering GPU cost efficiency.
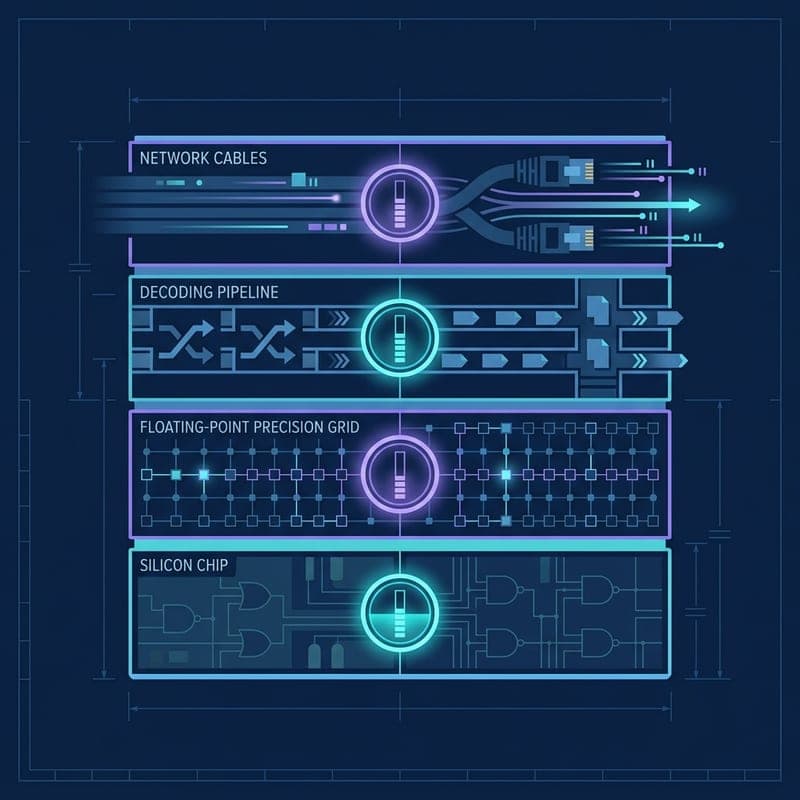
Four Stack-Layer Gains Prove Systems Engineering Now Rivals Scaling
Four advances in 48 hours — custom silicon, 4-bit quantization, speculative decoding, and a new transport protocol — show the inference stack delivering discontinuous gains.
OpenAI's Jalapeño Beats Blackwell on Inference Efficiency at Hot Chips
OpenAI's Jalapeño chip outperforms Nvidia Blackwell on tokens-per-user and throughput-per-kilowatt in SemiAnalysis' InferenceX benchmark.
Etched Raises $700M at $21B Valuation After Jane Street Deploys Its Hardware
Etched's valuation doubled from $10.3B to $21B in a month after quant firm Jane Street tested its inference chips and deployed a rack in its own datacenter.
NVIDIA TRTMC: Hugging Face to C++ TensorRT in Two Commands, No ONNX
NVIDIA's TensorRT Model Connect converts supported checkpoints to native C++ inference in two CLI commands, no ONNX export, across 76 model families.
Groq Raises $350M at $3.5B Valuation in Neocloud Pivot
Groq closes $350M at $3.5B — down from $6.9B — as it abandons custom LPU chips and operates Nvidia GPUs across 13 data centers.
NVIDIA Nemotron 3.5 Lightning: 30B Parameters, 3B Active
NVIDIA's Nemotron 3.5 Lightning activates only 3B of 30B parameters per token, targeting the execution layer of multi-model agent stacks.
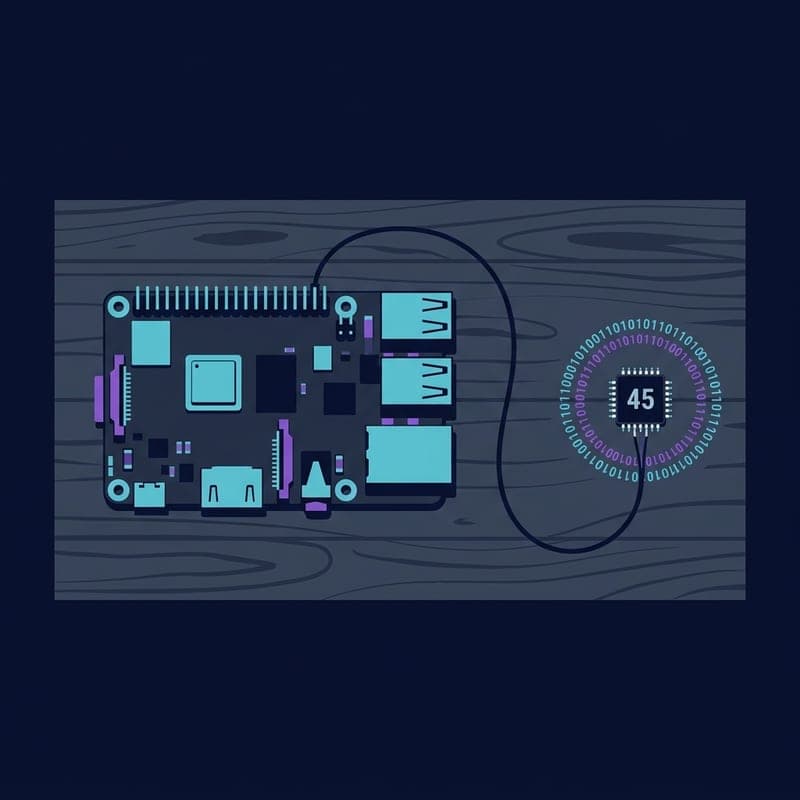
Needle 2: 45M-Parameter Tool-Calling Model in a 14MB Binary
Cactus Compute's Needle 2 runs a full inference session in 28MB of RAM, hits 500 tokens/sec on a Raspberry Pi 5, and needs no GPU.
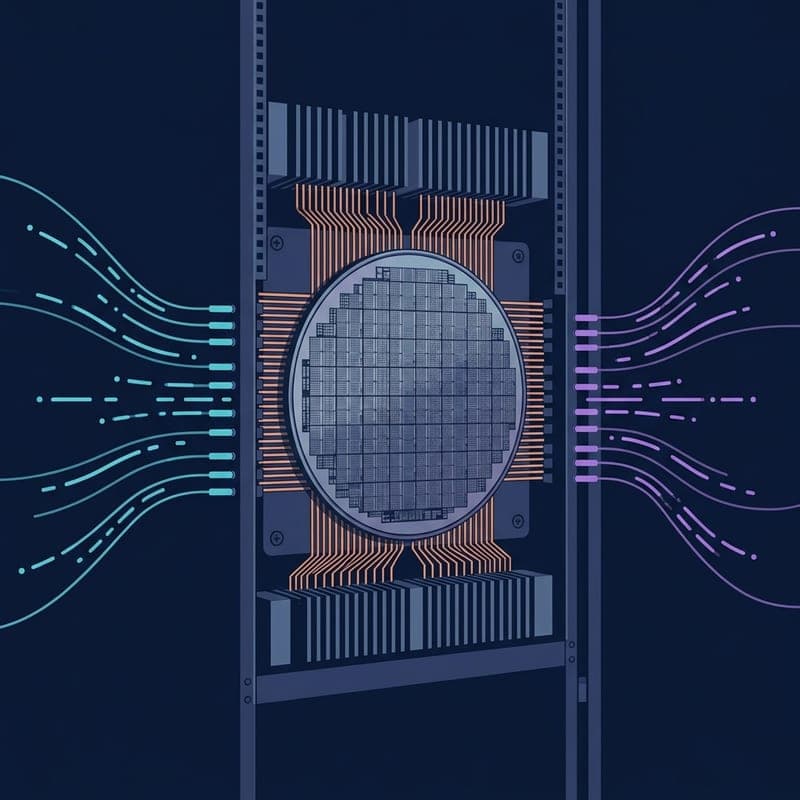
GPT-5.6 Sol Ultrafast Mode Delivers 750 Tokens/sec via Cerebras
OpenAI's new Ultrafast API tier runs GPT-5.6 Sol at up to 750 output tokens/sec — 14× Standard speed — powered by Cerebras silicon.
OpenAI Ultrafast Mode Hits 750 Tokens/sec on GPT-5.6 Sol
OpenAI's Ultrafast preview mode delivers up to 750 output tokens per second on GPT-5.6 Sol — 14x standard speed — via a Cerebras chip partnership.