
Author
Shan
Shan edits AI Mastery's daily reporting and evaluates new models, developer tools, and infrastructure through an engineering-first lens.
Shan edits AI Mastery's daily reporting and evaluates new models, developer tools, and infrastructure through an engineering-first lens.
Recent work
Inception Mercury 3: 1,068 Tok/s, 1M Context, 8 of 12 Benchmarks
Inception's diffusion LLM claims 1,068 tokens per second, a 1M-token context window, and wins on 8 of 12 self-reported benchmarks against GPT-6 Luna and Claude Haiku 5.5.
Build Stateful Web Research Agents with Claude Agent SDK
Run one-off and stateful Claude research agents that search the web, cite sources, and read multimodal inputs with the Anthropic Cookbook pattern.
Claude Haiku 5.5: 90% Price Cut, 1M Context, Adaptive Effort
Claude Haiku 5.5 drops to $0.10 per million input tokens, expands to a 1M context window, and adds adjustable effort—but migration breaks old sampling-parameter calls.
Perplexity SPACE Sandbox: 0 VM Escapes in 108 Red-Team Runs
Perplexity open-sourced SPACE, the Firecracker microVM sandbox behind Perplexity Computer: Rust 0.8.0, 0 escapes in 108 red-team runs, egress bypasses fixed.
Build a Titanic Data Analyst Agent with smolagents
Use smolagents CodeAgent to explore Titanic data, generate plots, and train an ML baseline from one natural-language prompt.
StepFun Opens 600B MoE Weights: 27B Active, 1M Context
StepFun's Step 5 Preview is now open weights: a 600B sparse MoE with 27B active parameters, 1M context, and a $1.00/$2.70 API.
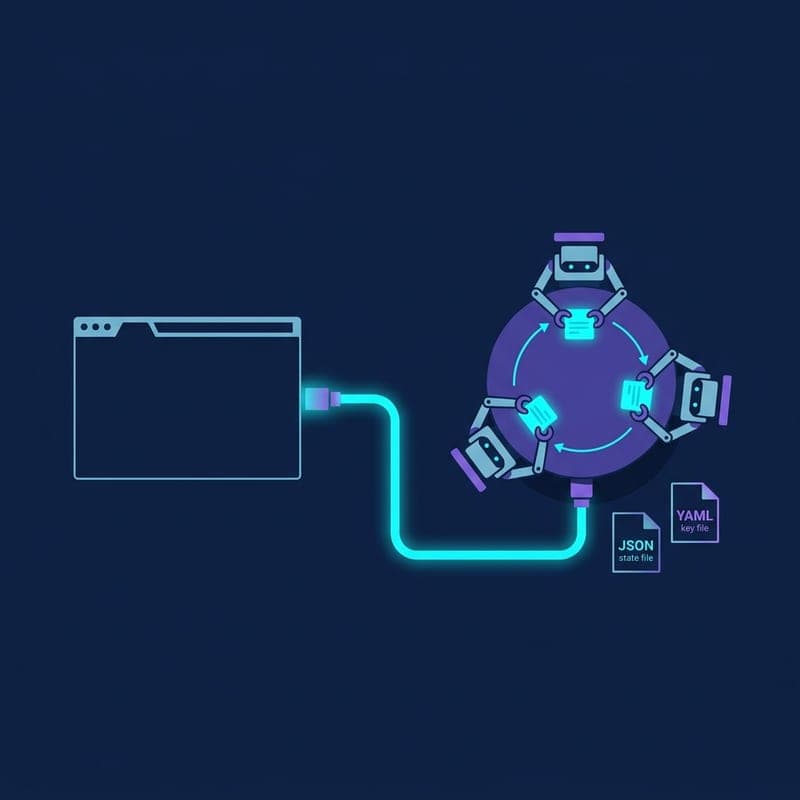
Run a Microsoft AutoGen Team as a FastAPI WebSocket App
Adapt Microsoft AutoGen's app_team.py into a FastAPI WebSocket endpoint that streams multi-agent chat, persists state, and serves a browser UI.
Meta's Muse Spark Open Puts 816B MoE on Two Mac Studios
Meta's open-weight 816B MoE activates 42B parameters, holds 1M context, runs on two M5 Ultra Mac Studios, and leads on MCP-Atlas but trails on coding.
NVIDIA Nemotron 3.5 Super VL: 120B MoE Runs on a Single GPU
NVIDIA's Nemotron 3.5 Super VL combines 120B total parameters with 12B active and runs the NVFP4 checkpoint on one DGX Spark, H200, or GB200.
Fine-Tune a Quantized Llama on GSM8K with PEFT LoftQ
A step-by-step walkthrough of the Hugging Face PEFT GSM8K LoftQ script: 4-bit NF4 loading, preprocessing, training, and exact-match accuracy.
Gemini 4 Argon Ships $2 Input, 1M Token Output
Google's Gemini 4 Argon launches with $2 per million input tokens, $10 per million output tokens, and a 1M-token output limit, undercutting frontier rivals on price.
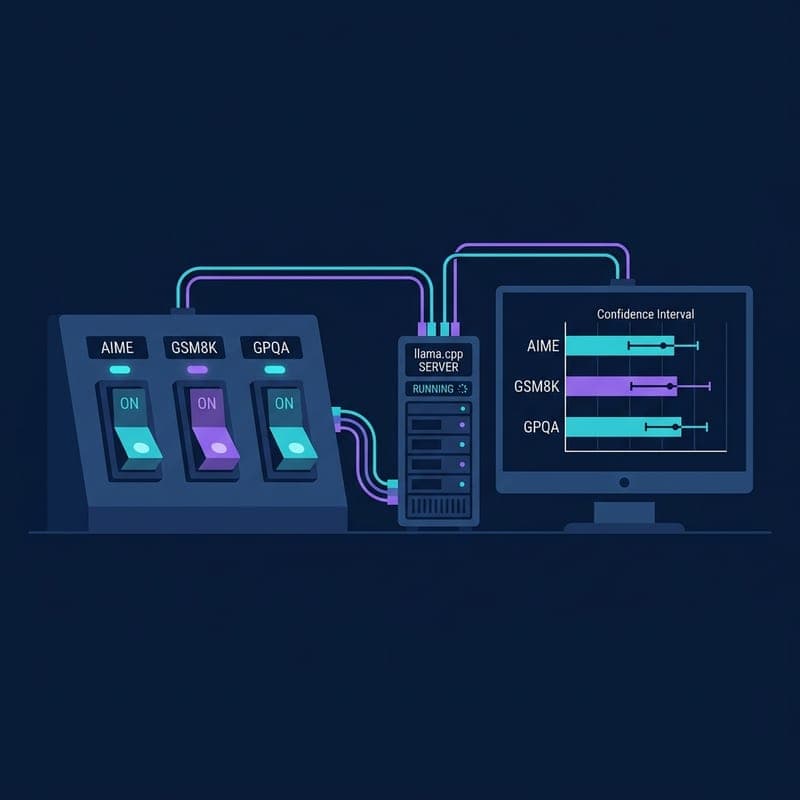
Benchmark Local Models with llama.cpp's llama-eval.py
Use llama.cpp's single-file eval harness to run reproducible AIME, GSM8K, and GPQA benchmarks against a local server with Wilson confidence intervals.