
NVIDIA
32 pieces on NVIDIA.
News & Analysis
NVIDIA Nemotron 3.5 Super VL: 120B MoE Runs on a Single GPU
NVIDIA's Nemotron 3.5 Super VL combines 120B total parameters with 12B active and runs the NVFP4 checkpoint on one DGX Spark, H200, or GB200.
Nemotron Scores 535.4 IOI and 30/42 IMO, Passing Gold in Both
NVIDIA reports one Nemotron family reached 535.4/600 on IOI 2026 and 30/42 on IMO 2026, above both gold thresholds.
Reflection Beam: 501B Parameters, 23B Active, 3–4x Less Compute Claim
Reflection's text-only 501B-parameter MoE activates only 23B parameters and claims 3–4x lower inference compute than leading Western open models.
Infrastructure Rewrites, Not Model Weights, Drive 2026 AI Gains
Four independent engineering efforts show runtime routing, service rewrites, and kernel fusion outperforming model compression on production AI systems.
cuDNN Graph API: Fusion, Autotuning, and Plan Reuse Explained
NVIDIA's cuDNN Frontend Graph API makes kernel fusion, engine selection, and compilation timing explicit — here's how each technique works.
NVIDIA PAIR Routes Local AI Requests Across Nodes, Cuts Demo Time 2x
NVIDIA's PAIR beta distributes inference across local GPU nodes via Ollama and LM Studio, showing ~2x faster completion in a three-node demo.
NVIDIA's CUDA Rust Brings Compile-Time Kernel Safety via Two Crates
NVlabs releases cuda-oxide (SIMT) and cutile-rs (Tile), making Rust a first-class GPU kernel language with borrow-checker-enforced aliasing safety.
Nvidia PAIR Federates Idle Home Computers Into Local AI Clusters
Nvidia's free, open-source PAIR software links idle home PCs and Macs into a distributed local inference cluster, announced at IFA 2026.
NVIDIA's Switchyard Routes LLM Traffic Between OpenAI and Anthropic APIs
NVIDIA open-sources Switchyard, an Apache 2.0 Rust proxy that translates and routes LLM traffic across OpenAI and Anthropic wire formats, including streams.
DLSS 5 Launches September 3rd, Needs 6x Frame Gen on RTX 5060
DLSS 5 officially arrives with NBA 2K27 on September 3rd, restricted to RTX 50-series GPUs and carrying a 50–60% performance penalty.
Nvidia's $3.5B MediaTek Bet Makes Custom Chips Depend on Nvidia Racks
Nvidia invests $3.5B in MediaTek so hyperscaler custom ASICs plug into NVLink Fusion — escaping the GPU but not the platform.
Nvidia's Vera Rubin Delivers 3x Storage Gains Beyond the GPU
Nvidia's Vera Rubin stack delivers up to 3x storage operation gains via the Vera CPU — shifting its moat from GPU silicon to data orchestration.
NVIDIA Earth2Studio: Custom Batched Ensemble Forecasting Pipeline
Build a full ensemble weather pipeline in Earth2Studio using low-level iterators, custom diagnostics, Zarr I/O, and fair CRPS verification — all in one Colab session.
Amazon Adds 2M More Nvidia GPUs After 5-Month Demand Surge
AWS triples its Nvidia GPU commitment to 3M+ chips spanning Blackwell Ultra, Rubin, and Rubin Ultra, with delivery across 2027–2028.
NVIDIA MPS Cuts ASR GPU Count from 16 to 4 on EC2
NVIDIA CUDA MPS on EC2 g7e.4xlarge delivers 92.1 RPS at 352 ms mean latency, reducing Heidi Health's GPU fleet 75% while holding sub-second SLAs.
Anthropic Signs $45B Nscale Deal for Vera Rubin Compute by 2027
Anthropic's $45B, six-year Nscale deal adds Vera Rubin capacity from a West Virginia data center, extending a compute spree that now spans six partners.
OpenAI's Jalapeño ASIC Beats Nvidia GB200/GB300 on Latency and Throughput
OpenAI's Jalapeño chip delivers 1.5–1.9× more AI work per watt and 1.7–3.6× lower latency than Nvidia GB200/GB300 across three models.
Perplexity Portable Computer: Full Agent Harness on DGX Spark, $0 Local Steps
Perplexity ships a full agentic harness on NVIDIA DGX Spark with zero per-token cost for local steps and OS-enforced sandboxing.
Nvidia Takes Minority Stake in Data Center Site Developer Cloverleaf
Nvidia acquires a minority equity stake in Cloverleaf Infrastructure, a 2024-founded power-site middleman, in a deal likely worth several hundred million dollars.
Nvidia's AVO Harness Takes Claude Opus 5 from 30% to 100% on ARC-AGI-3
Nvidia's custom AVO harness lifted Claude Opus 5 from 30% to 100% on ARC-AGI-3 — without changing the model at all.
Etched Raises $700M at $21B Valuation After Jane Street Deploys Its Hardware
Etched's valuation doubled from $10.3B to $21B in a month after quant firm Jane Street tested its inference chips and deployed a rack in its own datacenter.
Nvidia Invests $1.5B in SB Energy, Locks In Sole GPU Supply at Ports-Pike
Nvidia's $1.5B equity stake in SB Energy makes it the sole compute supplier at the OpenAI-linked Ports-Pike data center, backed by up to $105B in credit.
NVIDIA TRTMC: Hugging Face to C++ TensorRT in Two Commands, No ONNX
NVIDIA's TensorRT Model Connect converts supported checkpoints to native C++ inference in two CLI commands, no ONNX export, across 76 model families.
Groq Raises $350M at $3.5B Valuation in Neocloud Pivot
Groq closes $350M at $3.5B — down from $6.9B — as it abandons custom LPU chips and operates Nvidia GPUs across 13 data centers.
NVIDIA Nemotron 3.5 Lightning: 30B Parameters, 3B Active
NVIDIA's Nemotron 3.5 Lightning activates only 3B of 30B parameters per token, targeting the execution layer of multi-model agent stacks.
NVIDIA Nemotron 3.5 Lightning: 30B MoE with 3B Active Parameters
NVIDIA ships Nemotron 3.5 Lightning, a 30B MoE with 3B active parameters and 1M-token context, plus NeMo Switchyard for per-step agent routing.
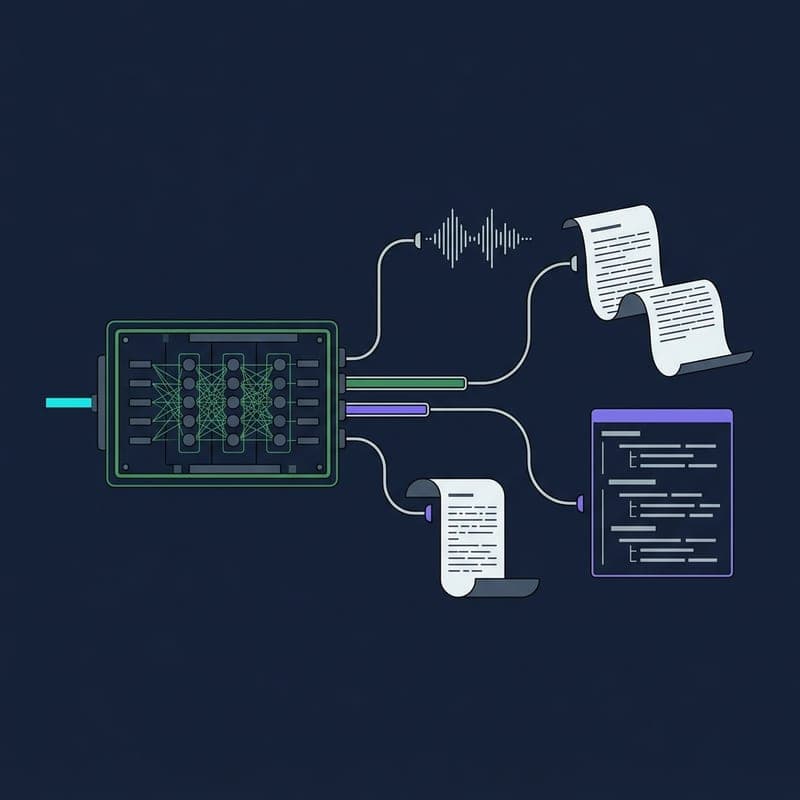
NVIDIA VoiceChat 11B: Open Full-Duplex Speech Model with 448 ms Latency
NVIDIA's NemotronLabs VoiceChat 11B unifies ASR, LLM, and TTS into one 11B model with 448 ms turn-taking and live tool calling.
NOOA: NVIDIA's Object-Oriented Agent Framework Explained
NVIDIA open-sources NOOA, a Python framework that collapses prompt templates, tool schemas, and workflow graphs into one class—with 82.2% on SWE-bench Verified.
Nvidia 'Largely Concedes' China AI Chip Market to Huawei Following Export Restrictions
CEO Jensen Huang admitted Nvidia has effectively exited the Chinese market due to tightening US export controls, allowing Huawei to solidify its dominance.
Nvidia Posts Record $58.3 Billion Profit, Rides Data Center Boom Driven by Agentic AI
Driven by the surge in agentic AI capabilities, Nvidia announced staggering quarterly growth, hauling in $81.6 billion in revenue and executing a massive stock buyback.
Nvidia Tightens Grip on AI Market with $95 Billion Supply Chain Bet
Nvidia is aggressively locking down the AI chip supply chain, committing nearly $100 billion to vendors to ensure hardware dominance and meet explosive demand.
Nvidia's Blackwell Architecture Finally Hits Global Data Centers
The much anticipated Blackwell chips are spinning up at massive scale, promising a dramatic reduction in AI inference costs.