
Evaluation
8 pieces on Evaluation, including 4 step-by-step guides.
Guides
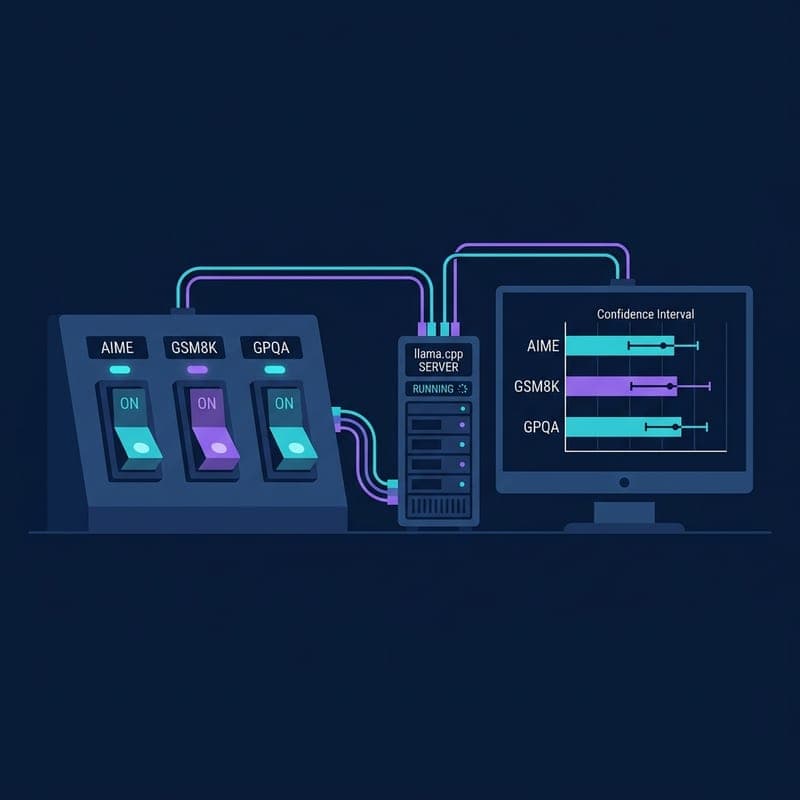
Benchmark Local Models with llama.cpp's llama-eval.py
Use llama.cpp's single-file eval harness to run reproducible AIME, GSM8K, and GPQA benchmarks against a local server with Wilson confidence intervals.
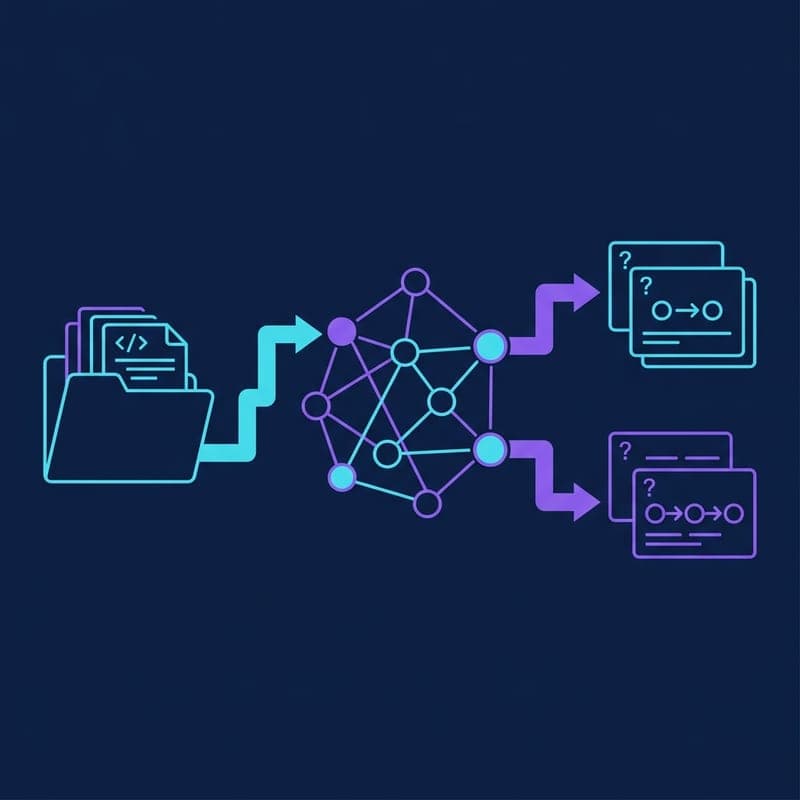
Generate Synthetic RAG Test Sets With Ragas
Build, save and reuse a Ragas knowledge graph to generate single-hop and multi-hop evaluation queries from Markdown documents.
Evaluate Multi-Turn Conversations with Ragas AspectCritic
Use Ragas AspectCritic to score multi-turn chatbot conversations on task completion, regulatory compliance, and brand voice with binary LLM judgements.
Mastering Advanced RAG Evaluation: From Basic Metrics to LLM-as-a-Judge
Learn how to systematically evaluate Retrieval-Augmented Generation (RAG) pipelines using the RAG Triad, Ragas, and LLM-as-a-Judge techniques.
News & Analysis
NEEDLE Benchmark Rebuilds Search Queries Every Hour to Block Label Leakage
Keenable AI's MIT-licensed NEEDLE benchmark regenerates web search queries from live public sources, eliminating the fixed answer keys agents can fetch or memorize.
ASR Benchmarks Are Gameable: 6 of 11 Top Models Reproduce Audio Errors
Hume AI tested 11 open-source ASR models and found six reproduce VoxPopuli's transcript errors even when audio contradicts them — exposing WER as a gameable metric.
LLM Judges Carry Nine Measurable Biases: What to Do
DHS 2026 research catalogues nine exploitable biases in LLM-as-judge pipelines and shows grounded evaluators as the structural fix.
Nine Measurable Biases That Corrupt LLM Judge Verdicts
A DHS 2026 workshop catalogued nine distinct biases in LLM-as-judge pipelines — and showed grounded evaluation as the structural fix.