
Quantization
8 pieces on Quantization, including 4 step-by-step guides.
Guides
Fine-Tune a Quantized Llama on GSM8K with PEFT LoftQ
A step-by-step walkthrough of the Hugging Face PEFT GSM8K LoftQ script: 4-bit NF4 loading, preprocessing, training, and exact-match accuracy.
Self-Hosting Your First LLM: Complete Hardware, Benchmark & Deployment Playbook
A complete engineering playbook for self-hosting production LLMs for AI agents: benchmark selection, quantization trade-offs, cloud GPU instance economics, and zero-switch proxy architecture.
Host and Run Qwen3.8-Flash Locally: Complete Unsloth and llama.cpp Deployment Guide
Run Qwen3.8-Flash locally on CPU, unified memory, or GPUs using Unsloth and llama.cpp with Multi-Token Prediction (MTP) for up to 1.7x faster inference.
Advanced LLM Compression: A Hands-on Implementation Guide for FP8, GPTQ, and SmoothQuant using llmcompressor
Stop deploying heavy FP16 models. Learn how to compress, calibrate, and benchmark instruction-tuned LLMs using FP8 dynamic, GPTQ W4A16, and SmoothQuant W8A8 quantization recipes with llmcompressor.
News & Analysis
ThinkingCap-Qwen3.8-27B Cuts Thinking Tokens 37.2% for 0.86pp Accuracy
BottleCap AI's fine-tune of Qwen3.8-27B drops thinking tokens 37.2% across 12 benchmarks, losing just 0.86pp of macro accuracy at xhigh effort.
2.4T-Parameter Qwen3.8 Runs on One Node With vLLM and NVFP4
AWS documents a single-node serving path for Qwen3.8-2.4T-A95B on a p6-b300 instance using NVFP4 quantization, cutting TTFT by nearly 60%.
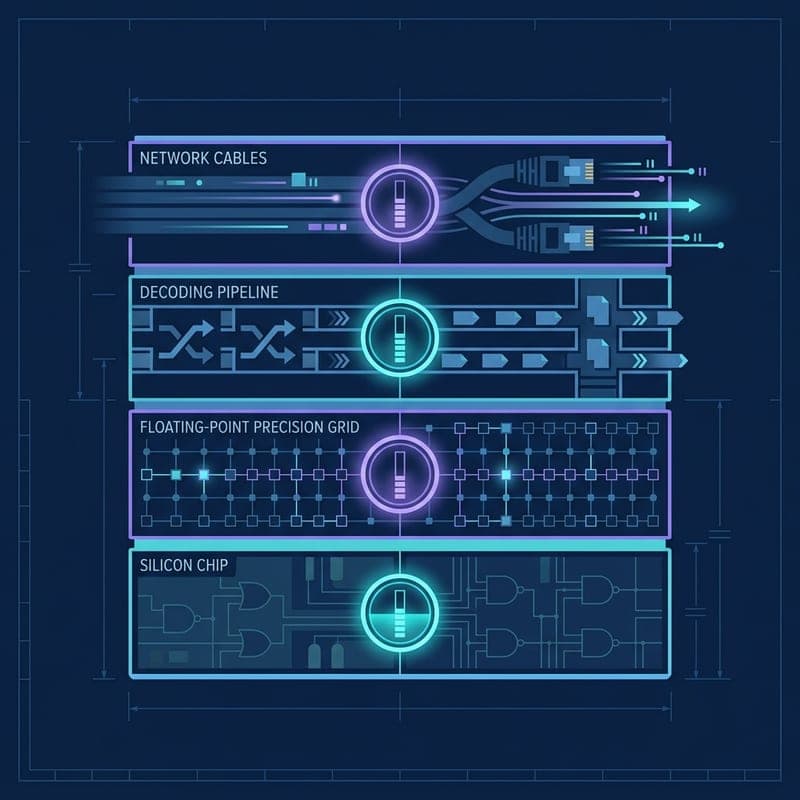
Four AI Systems Reports: Compare the Baseline Before the Speedup
Custom silicon, quantization, speculative decoding and RDMA solve different problems. Their reported gains need separate baselines and deployment checks.
4-Bit GPT-OSS 60B Beats Its Own BF16 Checkpoint on 7 of 9 Benchmarks
Multiverse reports seven benchmark gains over a recovered BF16 student. Its QAH paper limits the result to single runs and identifies a missing comparison.