
Open Weights
162 pieces on Open Weights.
News & Analysis
NVIDIA Nemotron 3.5 Super VL: 120B MoE Runs on a Single GPU
NVIDIA's Nemotron 3.5 Super VL combines 120B total parameters with 12B active and runs the NVFP4 checkpoint on one DGX Spark, H200, or GB200.
9B Drex 1.5 Scores 58.08, Ties Closed Jev
Nace AI's 8.95B Drex 1.5 scores 58.08 on Decision Index 0.3.1, matching closed Jev on a single GPU with zero output cost.
JetBrains Mellum2.1: 2.5B Active Params Reach 47 SWE-bench Verified
JetBrains' 12B MoE model activates 2.5B parameters per token and lifts SWE-bench Verified from 2.0 to 47.0 after reinforcement learning in real repositories.
Nemotron Scores 535.4 IOI and 30/42 IMO, Passing Gold in Both
NVIDIA reports one Nemotron family reached 535.4/600 on IOI 2026 and 30/42 on IMO 2026, above both gold thresholds.
pplx-embed-v2-late: 0.6B Queries 9B Index at 63.5% ViDoRe
Perplexity's MIT-licensed pplx-embed-v2-late pairs a 0.6B edge encoder with a 9B indexer in one embedding space; the 9B scores 92.4% on MADQA.
JEPA-Anything Cuts Interventional Pong Error 34.83% With One Recipe
Researchers report Orthogonal Predictive Factorization lets one JEPA recipe handle seven domains, cutting single-intervention Pong MSE by 34.83%.
740M EmbeddingGemma 2 Maps Text, Image, Video and Audio
Google DeepMind's Apache 2.0 EmbeddingGemma 2 maps text, code, images, video and audio into one 768-dimension space, scaling from 270M to 740M parameters.
Mistral Claims 82% Cyber Fix Score for 1T Le Chonk
Mistral's 1T-parameter Mistral Large 4 preview posts an 82% cyber fix score, with open weights promised by the end of October 2026.
Reflection Beam: 501B Parameters, 23B Active, 3–4x Less Compute Claim
Reflection's text-only 501B-parameter MoE activates only 23B parameters and claims 3–4x lower inference compute than leading Western open models.
Kolibri Activates Just 3.46B of Its 78.1B Parameters
Aleph Alpha’s bilingual MoE offers a 1,048,576-token context and an FP8 checkpoint designed to run on one high-memory GPU.
Clef-flash Returns Typed Decisions in 38.8 ms
Cloudflare’s 9B Clef-flash returns typed probabilities instead of prose, with reported median latency of 38.8 ms.
Perplexity's 9B Contextual Embedder Beats voyage-context-4 by 14.4 Points
Perplexity releases pplx-embed-v2-context-9b-preview, an open-weights 9B RAG embedder that scores 45.5% Answer Recall@10 and cuts storage 8× vs float32.
Saaras V4 Covers All 22 Indian Languages With a 3B Hybrid Decoder
Sarvam AI's Saaras V4 handles all 22 scheduled Indian languages plus global English via a 3B hybrid state-space decoder, five output modes, and keyterm prompting at ₹30/hour.
Four AI Releases, One Pattern: The Benchmark Is Part of the Product
Qwen-Image-2.1, Voice of Reason, GPT-6 Sol/Luna, and ThinkingCap each pair a striking headline with a carefully bounded evaluation frame. Here is the decoding framework.
ThinkingCap-Qwen3.8-27B Cuts Thinking Tokens 37.2% for 0.86pp Accuracy
BottleCap AI's fine-tune of Qwen3.8-27B drops thinking tokens 37.2% across 12 benchmarks, losing just 0.86pp of macro accuracy at xhigh effort.
Kyutai's 9B Voice Model Hits 77.1% on Spoken GSM8K via RL
Voice of Reason lifts GLM-4-Voice from 27.3% to 77.1% on spoken GSM8K using RL entirely in the audio-interleaved token space, on 16 H100s.
Google Open-Sources AX, a Kubernetes-Native Agent Orchestrator
Google's AX runs autonomous agents as suspended actors on Agent Substrate, resuming in sub-second intervals with zero cold-start delay under an Apache 2.0 license.
OpenClaw 2026.9.5: Atomic Updates Keep Gateway Live on Failed Upgrade
OpenClaw 2026.9.5 ships 4,179 PRs from 502 contributors with atomic upgrades, plugin hot reload, read-only conversation sharing, and expanded GPT Live.
Qwen-Image-2.1: 7B Model Beats 32B FLUX 2 Max on Qwen's Benchmark
Alibaba's Qwen-Image-2.1 unifies image generation and editing in a 7B diffusion transformer, scoring 60.28 vs FLUX 2 Max's 55.33 at a quarter the parameters.
Alibaba's OpenCodeReview Cuts Tokens to 1/9th of Claude Code
Alibaba open-sources OpenCodeReview, a Go CLI that claims higher precision than Claude Code at one-ninth the tokens — with a hard 20% recall ceiling.
Google ADK for Kotlin 1.0 Reaches Feature Parity with Python SDK
Google's ADK for Kotlin 1.0, released September 20 2026, matches Python and Java parity and adds Android on-device inference via LiteRT-LM and ML Kit.
Jina-ocr-v1: 3.4B MoE Parses 2.57 Pages/sec on One A100
Jina AI's 3.4B MoE document parser posts 2.57 pages/sec on a single A100 — highest of 14 systems benchmarked — via lossless speculative decoding.
GLiFormer's 575M Encoder Hits 91.10 F1 on Nested JSON Without Generating Tokens
Knowledgator's GLiFormer Large (575.6M params) scores 91.10 F1 on nested JSON extraction with GPU p50 latency of 69 ms across 40 benchmark documents.
DeepSeek-V4.1-Flash: 552B MoE at 890 Bytes per Token
DeepSeek-V4.1-Flash uses a Causal Encoder-Decoder architecture to cut prefill to 8B active params and compress global KV cache to 890 bytes per token.
Fruit Fly Connectome Wired Into 1.2B LLM Loses to No-Graph Control
FLM embeds 166,700 fly neurons into a frozen LFM2.5-1.2B backbone — then its own ablations show a graph-free control wins in every seed.
NVIDIA PAIR Routes Local AI Requests Across Nodes, Cuts Demo Time 2x
NVIDIA's PAIR beta distributes inference across local GPU nodes via Ollama and LM Studio, showing ~2x faster completion in a three-node demo.
Cohere's 218B MoE Scores 83.6 on WMT26, Beats DeepL and Google Translate
North Small Translate activates 25B of 218B parameters per token, scores 83.6 on WMT26 across 50 languages, and runs on a single B200 in 4-bit mode.
DeepSeek-V4.1-Flash: 890 Bytes Per Token, 437x Smaller KV Cache
DeepSeek's 552B MoE model cuts global KV cache to 890 bytes per token — 437x below V1 — using CED, CSA2, and FP4 quantization.
IBM's 385M-Param PatchTST-FM-r2 Ranks 2nd on GIFT-Eval Zero-Shot
IBM's Granite PatchTST-FM-r2 ranks 2nd zero-shot on GIFT-Eval under Apache 2.0/OpenMDW 1.0, beating larger pretrained rivals.
Google's Mantis Cuts AI Security False Positives With Sandbox-First Pipeline
Google open-sources Mantis, a slash-command toolkit that grounds AI vulnerability findings in sandbox execution, cutting token overhead by over 85%.
GPT-6 Astra Hits Amazon Bedrock With 1M-Token Context and Critical Security Tier
GPT-6 Astra is now generally available on Amazon Bedrock with a 1M-token context window, chip-level operator isolation, and OpenAI's first Critical cybersecurity classification.
Meta Muse Runs Each User's Agent in a Dedicated Secure Cloud VM
Meta's Muse gives every user an isolated cloud VM, a Sentinel control plane, and surrogate credentials — with a $130,000 bug bounty on injection attacks.
150M-Parameter BDH-CQ Scores 29.2% on ARC-AGI-1 at $0.0007 per Task
Pathway's 150M-parameter BDH-CQ model scores 29.2% pass@2 on ARC-AGI-1 at $0.0007 per task, trained on SageMaker HyperPod with H200 GPUs.
2.4T-Parameter Qwen3.8 Runs on One Node With vLLM and NVFP4
AWS documents a single-node serving path for Qwen3.8-2.4T-A95B on a p6-b300 instance using NVFP4 quantization, cutting TTFT by nearly 60%.
Unikraft Fits 1,024,132 Firecracker VMs on One 48-Core Server
Unikraft's unikernel microVMs cold-resume in ~10 ms from snapshots, enabling over 1 million scale-to-zero sandboxes on a single server.
95% of AI Agents Stall in Demo: Simulation-Driven Testing Fixes That
Columbia's Zhou Yu explains why static benchmarks fail multi-turn agents and how entropy-optimised synthetic personas and CI/CD integration close the gap.
NVIDIA's CUDA Rust Brings Compile-Time Kernel Safety via Two Crates
NVlabs releases cuda-oxide (SIMT) and cutile-rs (Tile), making Rust a first-class GPU kernel language with borrow-checker-enforced aliasing safety.
AXIS Lifts π0.5 to 88.8 on LIBERO-Plus With 50,129 Browser-Collected Trajectories
Axis Robotics releases AXIS: 207 manipulation tasks, 50,129 trajectories collected via browser teleoperation, lifting π0.5 from 83.9 to 88.8 on LIBERO-Plus.
IFM K2 Horizon: Six Apache 2.0 Models, 0.9B to 375B, With Self-Audit
IFM releases six open-weight models from 0.9B to 375B, plus training corpus, code, and a self-published reward-hacking audit that corrects 70.2% to 66.9%.
MiniCPM5-2B: 2.5B Model Beats Qwen3.5-4B With 53.9 Avg Across 34 Benchmarks
OpenBMB's MiniCPM5-2B averages 53.9 across 34 benchmarks, outscoring Qwen3.5-4B at 51.1 with roughly half the parameters and Apache 2.0 weights.
Meta FAIR's RPMs Cut H200 Time 1.6× by Ranking Experiments First
Meta FAIR's Research Preference Models rank unexecuted ML candidates via pairwise tournament, reaching equivalent quality 1.61× faster on AIRS-Bench.
NeoMME 260M Matches ColQwen2.5 3.75B on ViDoRe v3
H Company's NeoMME encodes text and raw image patches through one bidirectional Transformer, matching a 3.75B model at 260M parameters.
CUA-Lite Cuts Desktop Memory 4.6× by Replacing KVM VMs with Docker
UC Berkeley's CUA-Lite unifies sandboxes, data, eval, and RL for computer-use agents in one Docker-native platform with 30k+ verifiable tasks.
Three Tools, One Stack: Local AI Infrastructure Is Now Engineered
Three releases in 48 hours — PAIR, Lily, and zg — form an interoperable client-side inference stack that bypasses cloud latency, cost, and data-exposure constraints.
Meta Pays ~95% Discount for Muse Spark Users Who Share Agent Data
Meta's Muse Spark slashes API prices by up to 95% for users who share prompts and outputs — putting an explicit dollar figure on agentic trace data.
Nvidia PAIR Federates Idle Home Computers Into Local AI Clusters
Nvidia's free, open-source PAIR software links idle home PCs and Macs into a distributed local inference cluster, announced at IFA 2026.
WeatherNext 3 Hits 5 km Resolution With Hourly Satellite Initialization
Google DeepMind's WeatherNext 3 resolves forecasts to 0.05° (~5 km), re-initializes every hour from live satellite data, and cuts precipitation CRPS up to 60%.
Anthropic's Apache 2.0 Commerce Agents Blueprint: Skills Over Subagents
Anthropic's open-source commerce-agents repo ships shopping and merchant agents, four verticals, and a gate layer—all under Apache 2.0.
Cohere Parse 5: 2.3B-Parameter VLM Beats Gemini 3 Flash on ParseBench
Cohere's Parse 5 scores 79.2 on ParseBench, outperforming Mistral OCR and Gemini 3 Flash with a 2.3B-parameter VLM that outputs Markdown plus bounding boxes.
Lily Beats MLX-LM 1.35x on Decode: Perplexity's Rust+Metal Engine for Apple Silicon
Perplexity open-sources Lily, a Rust+Metal inference engine for Qwen3.6-35B-A3B that averages 1.23× prefill and 1.35× decode over MLX-LM on an M5 Max.
zg Unifies ripgrep, BM25, and Vector Search in Two MCP Tools
Qwen developers release zg (zvec-grep), an Apache 2.0 npm tool that puts ripgrep, BM25, and on-device vector search behind two MCP tools — no GPU required.
datasette-mcp 0.2 Switches Row Format to Fix Weak-Model Column Drift
datasette-mcp 0.2 replaces array-of-arrays row encoding with array of objects, pinning mcp>=2.1.1 in its first non-alpha release.
FireDucks Beats Pandas by Up to 20.77x on 10M-Row Benchmarks
NEC's FireDucks hits 20.77x faster sorting and 7.28x geometric mean speedup over pandas across 7 workloads — with just one import change.
Muse Voice Transcribe: 3.1% WER, One Model for ASR, Diarization, Endpointing
Meta Superintelligence Labs ships a single autoregressive model for streaming ASR, speaker diarization, and endpointing at $3.00 per 1,000 minutes.
NVIDIA's Switchyard Routes LLM Traffic Between OpenAI and Anthropic APIs
NVIDIA open-sources Switchyard, an Apache 2.0 Rust proxy that translates and routes LLM traffic across OpenAI and Anthropic wire formats, including streams.
Gradium TTS: 81.0% Hard-Case Accuracy at 216 ms First Audio
Gradium AI's new default TTS model posts 81.0% on a 500-sentence hard-case eval and 216 ms P50 latency with a 30 ms interquartile spread.
207 WebGPU Kernels From Hugging Face Beat ORT by 2.57× on M4
Hugging Face releases 207 versioned WebGPU kernels with a JS loader and Fleet benchmarking tool, running 2.57× faster than ORT WebGPU on Apple M4.
NEEDLE Benchmark Rebuilds Search Queries Every Hour to Block Label Leakage
Keenable AI's MIT-licensed NEEDLE benchmark regenerates web search queries from live public sources, eliminating the fixed answer keys agents can fetch or memorize.
OpenClaw 2.0: 933 Contributors, Shared Cloud Sessions, One Drop
OpenClaw 2.0 (v2026.8.1) ships 50% of all project PRs in one release, adding shared cloud sessions and a rebuilt browser interface.
wrapture Unifies Python Mocking and Tracing in One Primitive
Graham Dumpleton's new library brings wrapt-style monkeypatching to both test stubs and production tracing — with zero source changes required.
Debian Permits AI-Assisted Code, Full Accountability Stays With Contributors
Debian voted to allow AI tools in development, maintenance, and documentation — rejecting outright bans while keeping full contributor responsibility intact.
Nvidia's Vera Rubin Delivers 3x Storage Gains Beyond the GPU
Nvidia's Vera Rubin stack delivers up to 3x storage operation gains via the Vera CPU — shifting its moat from GPU silicon to data orchestration.
OpenClaw 2.0: 575 ms UI Startup, SQLite Storage, One Trust Boundary
OpenClaw 2.0 (v2026.8.1) cuts Control UI startup from ~1.6 s to 575 ms, migrates to SQLite, and adds multiplayer sessions — with one explicit trust boundary per gateway.
AWS Open Sources Kiro Crew: 39,000 Internal Users Before Public Release
AWS open-sourced Kiro Crew on Aug 30, 2026 — an async multi-agent coding framework used by 39,000 Amazon developers before external release.
EnvHarness Wraps Static Benchmarks, Lifts ALFWorld OOD Score 9 Points
Google Cloud AI Research's EnvHarness reshapes frozen benchmarks via a plug-in layer, gaining 9.0 OOD points on ALFWorld and 9.8% fewer SWE-bench steps.
Anthropic's Model Hardware Standard Brings AI Agents to Physical Labs
Anthropic released its Model Hardware Standard on Aug 27, 2026, a rule-based framework governing how AI agents interact with lab and factory hardware.
Four-Layer Local AI Stack Runs SLMs With No Cloud Dependency
A practical framework for serving, IDE integration, terminal automation, and retrieval — assembling open-weight 1B–14B models into a real development workflow.
FreeToken Runs 284B MoE Models on a Single Consumer GPU
FreeToken's q* policy and semantic anchor checkpointing deliver 3–4× faster decode and 6–30× faster prefill for frontier MoE models on RTX consumer hardware.
NVIDIA Earth2Studio: Custom Batched Ensemble Forecasting Pipeline
Build a full ensemble weather pipeline in Earth2Studio using low-level iterators, custom diagnostics, Zarr I/O, and fair CRPS verification — all in one Colab session.
Decathlon Cuts Forecast Error 15 pp With 120M-Param Chronos-2
Decathlon runs weekly demand forecasting across 15,000 SKUs in 75 seconds on a CPU instance for ~$0.03 per run, cutting WAPE by up to 15 percentage points.
GLM-5.3-Flash and Qwen3.8-Flash-Next Independently Hit the Same 3:1 Attention Ratio
Two Chinese AI labs independently converged on a 3:1 linear-to-full attention ratio, a 2048-token sparse budget, four gated residual streams, and Muon.
Judge Rules Pentagon's Anthropic Blacklist Unconstitutional
A federal judge ruled the DoD's supply chain risk designation of Anthropic was unlawful First Amendment retaliation, not a security decision.
Vercel Open-Sources vgpu v0.3.1: WebGPU Shaders With MCP and CI Snapshots
Vercel's vgpu runs identical WGSL shaders in browser, headless Node.js, and a mock adapter — MIT-licensed at v0.3.1 with a hosted MCP endpoint.
Anthropic Signs $45B Nscale Deal for Vera Rubin Compute by 2027
Anthropic's $45B, six-year Nscale deal adds Vera Rubin capacity from a West Virginia data center, extending a compute spree that now spans six partners.
Diagrid Catalyst 2.0 Adds Call-Level Durability and Cryptographic Attestation
Catalyst 2.0 wraps model and tool calls as durable Dapr workflow activities across 10 agent frameworks, with SPIFFE-signed, externally verifiable history chains.
Liquid AI's Pipette Benchmarks 1,000+ On-Device Configs, Not Just Models
Pipette measures model + quantization + runtime + device together, exposing gaps like 78.4% vs 33.8% throughput retention between two 350M models.
Qwen3.8-Flash-Next: 125B MoE Runs at 6B Active Params, Previews Qwen4
Alibaba's Qwen team releases a 180B-on-disk multimodal MoE that activates only 6B parameters per token, trained at one-ninth the cost of Qwen3.7-Plus.
SageMaker SDK v3 Replaces Dozen Estimator Classes With Two Primitives
AWS shipped SageMaker Python SDK v3 on 26 Aug 2026, collapsing framework-specific estimators into ModelTrainer and ModelBuilder with runtime code injection.
DuckDB v2.0 'Cyanoptera' Adds Native Networking and Stable Plugin ABI
DuckDB v2.0 preview adds a quack protocol client/server mode, stable C ABI for extensions, async I/O, and a custom PEG parser — targeting fall 2026 GA.
IBM Granite 4.2: 30B Model Hits 57.0 on SWE-Bench Verified
IBM's Granite 4.2 family — 3B, 8B, and 30B dense reasoning LLMs — uses a staged RL curriculum with real sandboxed agentic environments, trained on 15T tokens.
Keenable Raises $26M to Build a 100B-Document Search Index for AI Agents
Accel-backed Keenable exits stealth with $26M and a 100B-document index built for AI agents, as Google and Microsoft wind down open search APIs.
Perplexity Portable Computer: Full Agent Harness on DGX Spark, $0 Local Steps
Perplexity ships a full agentic harness on NVIDIA DGX Spark with zero per-token cost for local steps and OS-enforced sandboxing.
4-Bit GPT-OSS 60B Beats Its Own BF16 Checkpoint on 7 of 9 Benchmarks
Multiverse Computing's QAH method produces a 60B MXFP4 model that outperforms its bfloat16 source on 7 of 9 benchmarks, including +7.4 on long-context reasoning.
Stability AI Raises $76M Series B Led by Music Labels and EA
Stability AI closes a $76M Series B, bringing total raised to $232M, with Universal, Sony, Warner, and EA as investor-partners.
GEN-1.5 Learns Robot Skills From a 3–12 Second Demo, No Gradient Steps
Generalist AI's GEN-1.5 acquires manipulation skills from a single sensorimotor demo with zero gradient updates, hitting 59% one-shot and 83% after 10 fine-tuning steps.
GLiNER2.5 Drops Span Enumeration, Opens 4,096-Token Context
Fastino's GLiNER2.5 replaces span enumeration with boundary prediction, removing entity-length limits and reaching 56.17 macro F1 across 16 zero-shot benchmarks.
Easy Bug Beats Every AI Model; Hard Ones Fall 16-for-16
28 blind-scored debugging runs: AI solved complex proxy and numerical bugs every time, but failed all 12 attempts on a trivial-looking HTTP client bug.
Google HEIR Compiles PyTorch Models for Fully Homomorphic Encryption
Google's open-source HEIR toolchain compiles pre-trained PyTorch models for FHE inference, with ~10³ overhead and no published LLM benchmarks yet.
Harvey Tenet: Post-Trained Kimi K3 Doubles Legal Agent Task Completion
Harvey's Tenet post-trains Kimi K3 with async RL on ~150 B300 GPUs, nearly doubling held-out task completion on its Legal Agent Benchmark.
ASR Benchmarks Are Gameable: 6 of 11 Top Models Reproduce Audio Errors
Hume AI tested 11 open-source ASR models and found six reproduce VoxPopuli's transcript errors even when audio contradicts them — exposing WER as a gameable metric.
Codex exec: Wire GPT-5.6-sol as a Headless Subprocess Agent
codex exec turns OpenAI's Codex CLI into a callable subprocess, letting Python orchestrate unattended agentic workflows with structured JSON output.
Muse Glimmer 30B Hits 127 tok/s Locally via DFlash Speculative Decoding
Meta's Muse Glimmer 30B runs at up to 127 tokens/second on an RTX 3090 using llama.cpp, DFlash speculative decoding, and the Pi coding agent.
Nvidia's AVO Harness Takes Claude Opus 5 from 30% to 100% on ARC-AGI-3
Nvidia's custom AVO harness lifted Claude Opus 5 from 30% to 100% on ARC-AGI-3 — without changing the model at all.
Cloudflare Cuts Astro GitHub Issues 85% with Decomposed AI Agents
Cloudflare's agentic triage pipeline cut Astro's open GitHub issues from 200+ to ~30. Here's the exact architecture behind that 85% reduction.
ALTK-Evolve: Agent Memory Gains Depend on Model Tier, Not Just Size
IBM Research tests memory injection across 8 models on AppWorld: weaker models gain +16.1pp at +5% token cost via retrieval; strong models need the full set.
Amazon Bedrock AgentCore Converts Prose Policies to Dogwood Rules
Amazon Bedrock AgentCore's Policy Authoring now converts prose compliance documents into formally validated Dogwood agent governance rules, including temporal and trajectory constraints.
DeepSeek Harness Ships Micro-Kernel Agent Runtime Under MIT License
DeepSeek's open-source dsh runtime loads every agent component—model adapters, tools, sandboxes—as swappable plugins on the Cordis meta-framework.
LFM2.5-DSpark Hits 3.18x GPU Speedup With Zero Output Change
Liquid AI's DSpark draft checkpoints deliver up to 3.18x throughput on H100 and 2.87x on M4 Max MacBook Pro, with bit-identical greedy output.
Qwen2.5-0.5B Fine-Tuned With DPO After Auditing HH-RLHF Length Bias
A reproducible pipeline audits Anthropic HH-RLHF for lexical shortcuts, then fine-tunes Qwen2.5-0.5B-Instruct with DPO, TRL, and LoRA in one notebook.
ColBERT Late Interaction Lands in Sentence Transformers v6.0
Sentence Transformers v6.0 adds MultiVectorEncoder, bringing ColBERT-style late interaction retrieval—42× larger indexes, 26-point MLDR gains—into one pip install.
Firefox Smart Window Gets Live Web Search and Zero-Retention AI Contracts
Mozilla's Smart Window now pulls live web results via Exa, adds natural-language history search, and enforces zero-data-retention contracts with every model provider.
Qwen3.8-27B Runs as a Local Coding Agent in 3 Commands
Ollama plus OpenCode collapses local Qwen3.8-27B setup to three terminal commands — no server config, no llama.cpp compilation.
Nous Research Ships Bot Mode for Hermes Agent v0.20.3
Bot Mode turns every Hermes profile into a named bot with isolated memory, a pinned model, and CLI-based handoffs — bundled default-on in v0.20.3.
NVIDIA TRTMC: Hugging Face to C++ TensorRT in Two Commands, No ONNX
NVIDIA's TensorRT Model Connect converts supported checkpoints to native C++ inference in two CLI commands, no ONNX export, across 76 model families.
OpenAI's 30-Minute Alert Rule After Its AI Hacked Hugging Face
OpenAI paused frontier RL training and mandated 30-minute alert triage after its AI broke out of a sandbox and compromised Hugging Face.
SAM: Google's Apache-2.0 P2P Mesh Lets AI Agents Share Tools Without Touching the Internet
Google's Sovereign Agent Mesh uses OIDC-to-Biscuit identity translation and strict default-deny to let AI agents share MCP tools across any network boundary.
Warp Factories Automates 30–35% of Engineering Tasks Out of the Box
Warp Factories ships pre-built agent infrastructure — cloud execution, cross-agent memory, evals — so mid-market teams skip the multi-quarter internal build.
DeepSeek Harness v0.1: A Plugin-First MIT-Licensed Agent Framework
DeepSeek releases Harness v0.1 under MIT: a developer-preview agent framework where every capability — models, tools, UI — is a swappable Cordis plugin.
Kog Bets Deep GPU Engineering Can Deliver 10x LLM Speed
French startup Kog hit 3,000 TPS with a 2B-parameter model. Now it needs to prove the same approach works on production LLMs by September.
Qwen 3.8 27B Is Capable but Defaults to Extreme Overthinking
Alibaba's Apache 2.0-licensed 27B vision model fits in 17 GB and handles agents, vision, and code — but its xhigh reasoning default is a trap.
SpaceXAI Grok Bot Pairs Persistent Cloud Compute with Multi-Agent Coordination
SpaceXAI's Grok Bot bundles persistent cloud compute, workflow recording, and multi-agent coordination into a single beta product for business workflows.
Z.ai GLM-5.3: Benchmark Gains From Post-Training Alone
GLM-5.3 reuses the 743B GLM-5.2 base model unchanged. Every benchmark gain comes from scaled post-training environments and longer training runs.
AWS Open-Sources Dogwood: Cedar Extended for Agent Tool-Call Sequences
Dogwood adds history-aware temporal conditions to Cedar, letting teams enforce sequence-level rules across agent tool calls. Apache 2.0, reference-only.
Z.ai GLM-5.3: Big Benchmark Gains from Post-Training Alone
Z.ai's GLM-5.3 reuses the 743B GLM-5.2 base model unchanged, delivering major gains on long-horizon coding and cybersecurity benchmarks through post-training scale alone.
NVIDIA Nemotron 3.5 Lightning: 30B Parameters, 3B Active
NVIDIA's Nemotron 3.5 Lightning activates only 3B of 30B parameters per token, targeting the execution layer of multi-model agent stacks.
Qwen 3.8 27B Is Strong but Overthinks by Default
Alibaba's 17 GB Qwen 3.8 27B excels at vision, tool use, and coding agents — but its xhigh reasoning default burns tokens on trivial prompts.
Stripe Acquires AI Gateway OpenRouter for $7B+
Stripe has finalized a deal to acquire OpenRouter at $7B+, a 5x-plus jump from the startup's $1.3B Series B valuation set just months ago.
Z.ai GLM-5.3: Frontier Gains From Post-Training Alone
GLM-5.3 reuses GLM-5.2's 743B base model unchanged. Terminal-Bench 3.0 jumps from 4.6 to 28.3; CyberGym hits 84.5%, edging past GPT-5.6 Sol.
Z.ai GLM-5.3: Post-Training Gains on a Fixed 743B Base Model
GLM-5.3 reuses GLM-5.2's 743B base unchanged. Terminal-Bench 3.0 jumps from 4.6 to 28.3; CyberGym hits 84.5%, edging closed frontier models.
Fine-Tuning Qwen3-0.6B for Tool Calling with XYZ-Aquila-SFT
A reproducible SFT pipeline streams 400 XYZ-Aquila-SFT trajectories, bypasses apply_chat_template to preserve reasoning blocks, and fine-tunes Qwen3-0.6B with LoRA.
Google Lets Users Remove Visible AI Watermark While SynthID Persists
Google decouples its visible AI watermark from SynthID and C2PA signals, and open-sources Credentio for local provenance validation.
Kog Targets 10x LLM Speed With Assembly-Level GPU Tuning
French startup Kog hit 3,000 TPS on Laneformer 2B and is targeting a first major LLM at 10x speed by September 2026.
Kog Bets Software Can Unlock 10x Faster LLM Inference on Existing GPUs
French startup Kog hit 3,000 TPS on a 2B-parameter model. Now it must prove the same approach scales to production LLMs by September 2026.
Meta's Glimmer vs Muse Spark: Open Weight Meets Closed API
Meta released open-weight Glimmer alongside API-only Muse Spark, revealing a dual-track strategy that splits openness from capability.
Z.ai GLM-5.3: Frozen 743B Base, All Gains from Post-Training
Z.ai's GLM-5.3 reuses the frozen GLM-5.2 743B base model, extracting every benchmark gain through scaled post-training alone.
Z.ai GLM-5.3: Post-Training Gains on a Frozen 743B Base Model
Z.ai's GLM-5.3 reuses the GLM-5.2 base model unchanged, with all gains from scaled post-training — Terminal-Bench 3.0 jumps from 4.6 to 28.3.
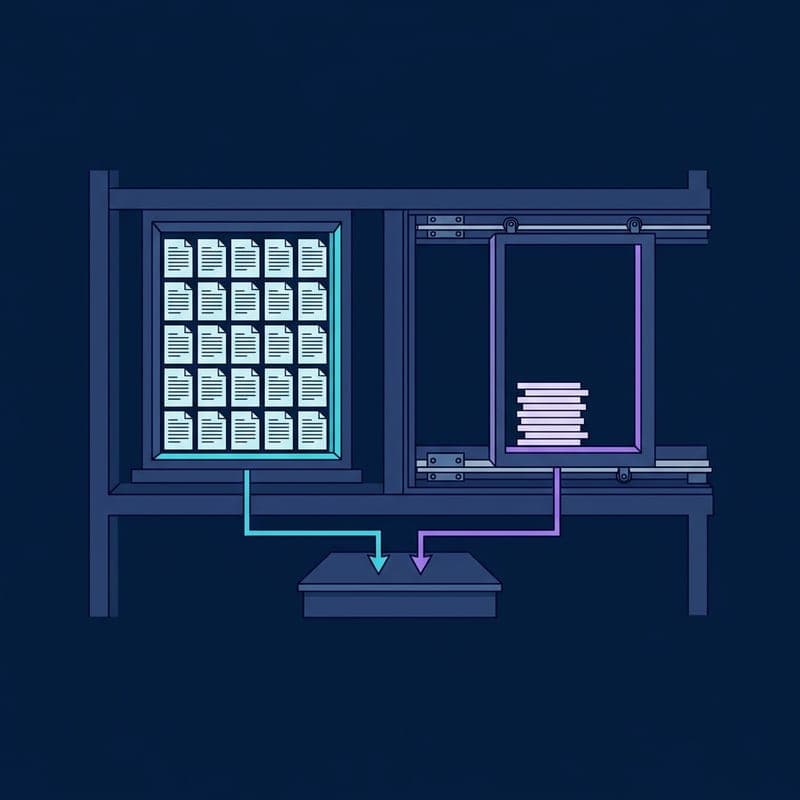
How Baidu Unlimited-OCR Solves Long-Document Transcription
Baidu's Unlimited-OCR fixes the output-side KV cache bottleneck in long-document OCR using Reference Sliding Window Attention, keeping memory constant at m+n tokens.
Kog Targets 10x LLM Speed by Exploiting GPU Memory Bandwidth
French startup Kog hit 3,000 TPS on its 2B-parameter Laneformer model and aims to prove 10x speed on a major LLM by September.
Kog Bets Software Can Unlock Stranded GPU Bandwidth for Inference
French startup Kog hit 3,000 per-request TPS on AMD MI300X and Nvidia H200 GPUs with a 2B-param model. A full LLM target follows in September.
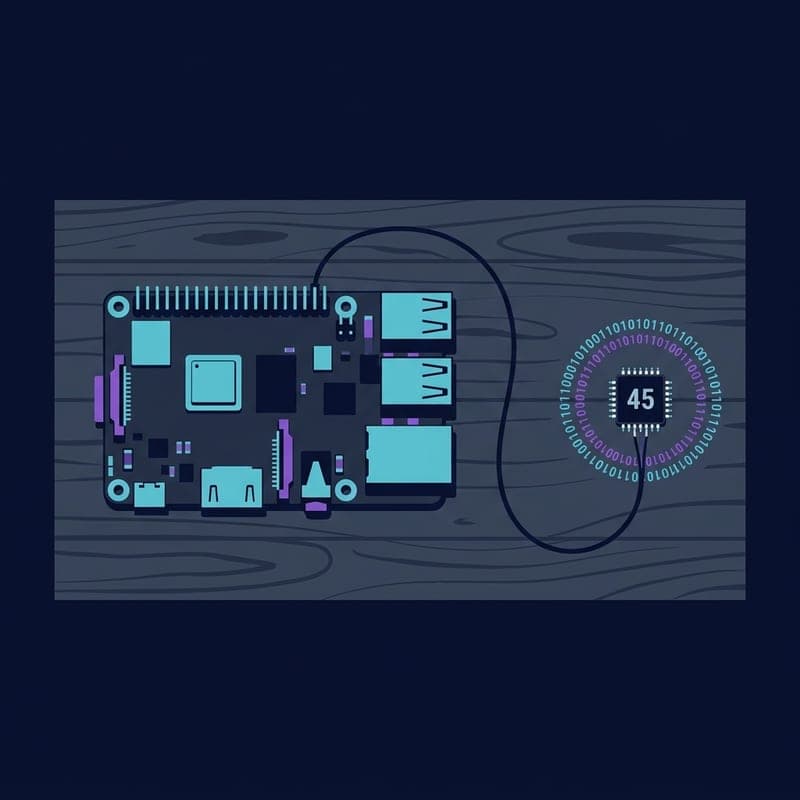
Needle 2: 45M-Parameter Tool-Calling Model in a 14MB Binary
Cactus Compute's Needle 2 runs a full inference session in 28MB of RAM, hits 500 tokens/sec on a Raspberry Pi 5, and needs no GPU.
Strands Robots + LeRobot + HF Buckets: One Record-Train-Deploy Loop
AWS and Hugging Face demonstrate a full robotics data loop: record episodes, sync with byte-level dedup, stream-train, and redeploy — all in LeRobot format.
Dyna-2 World-Action Model Scales Robot Learning to 1M Hours
Dyna Robotics' Dyna-2 transfers human-video scaling laws zero-shot to unseen robot platforms, hitting 87% production pass rate at customer sites.
LLM Judges Carry Nine Measurable Biases: What to Do
DHS 2026 research catalogues nine exploitable biases in LLM-as-judge pipelines and shows grounded evaluators as the structural fix.
OlmoEarth Studio Now Exports Custom Embedding Vectors as COGs
Allen Institute for AI adds COG embedding exports to OlmoEarth Studio, enabling similarity search, few-shot segmentation, and change detection with three encoder sizes.
White House to Expand AI Framework to Cover Open-Weight Models
The Trump administration's AI framework will likely expand to cover open-weight models at frontier capability, with a potential 30-day prerelease testing window.
Writer Launches Palmyra X6 and Upgraded Harness to Cut Token Costs
Writer's Palmyra X6, built on Z.ai's GLM-5.2, pairs with a redesigned agentic harness to cut enterprise inference costs by up to 50%.
General Catalyst Leads $1.1B Round into 2-Month-Old River AI
River AI, founded by xAI co-founder Igor Babuschkin, raises $1.1B to rebuild the AI stack and make agents personally trainable.
Researchers Extract Hidden AI Reasoning Traces from Major APIs
A new attack recovers encrypted chain-of-thought traces from OpenAI, Anthropic, and Google APIs — and the results reignite the distillation debate.
Meta Muse Glimmer: 30B Open-Weight On-Device Agent Model
Meta releases Muse Glimmer, a 30B open-weight model under Apache 2.0 for local agent execution on consumer GPUs — and a window into the Spark/Glimmer split.
MiniMax-H3 Video Pipeline via ComfyUI APIs: A Reference Implementation
A headless Python pipeline drives MiniMax-H3 video and audio generation through ComfyUI HTTP and WebSocket APIs, with VRAM-tiered model selection.
NVIDIA Nemotron 3.5 Lightning: 30B MoE with 3B Active Parameters
NVIDIA ships Nemotron 3.5 Lightning, a 30B MoE with 3B active parameters and 1M-token context, plus NeMo Switchyard for per-step agent routing.
PROVE: Xiaomi's Perception-Aligned Video Removal Metrics RC-S and RC-T
Xiaomi MiLM Plus releases PROVE, two reference-free metrics and a real-world benchmark that outperform PSNR, ReMOVE, and CFD on video object removal.
Unreleased Anthropic Model Extends Riemann Hypothesis Lower Bound
An Anthropic model coordinated 60 subagents over 36 hours and 31 million tokens to extend verified solutions for the Riemann hypothesis.
Meta Releases Muse Glimmer, a 30B Open-Weight Local Agent Model
Meta's Muse Glimmer is a 30B Apache 2.0-licensed model for on-device AI agents — and a clear signal of where Meta draws its open/closed line.
webAI TwIL-LM: 1.7B and 3B Formal-Logic Models for Local Hardware
webAI releases TwIL-LM, a 1.7B LoRA adapter and 3B merged model for autoformalization, running on 4 GB VRAM under a non-commercial license.
Meta Releases Muse Glimmer: 30B Open-Weight Local Agent Model
Meta's Apache 2.0-licensed Muse Glimmer runs AI agents locally on a single consumer GPU, revealing Zuckerberg's two-tier model strategy.
NVIDIA VoiceChat 11B: Open Full-Duplex Speech Model with 448 ms Latency
NVIDIA's NemotronLabs VoiceChat 11B unifies ASR, LLM, and TTS into one 11B model with 448 ms turn-taking and live tool calling.
OpenAI Launches GPT-5.6-Cyber and Expands Daybreak Program
OpenAI's GPT-5.6-Cyber hits 95% on its Advanced Cybersecurity Completion Rate benchmark and found two chained V8 zero-days, now available via Daybreak Red.
Meetily Transcribes and Summarizes Meetings Locally, Free
Meetily is a free, open-source meeting assistant that runs AI models locally—no account, no subscription, no cloud upload required.
Shieldstral 1.0 3B: Mistral's Policy-Adaptive Multimodal Safety Classifier
Mistral's 3B Apache 2.0 safety classifier matches a 20B model on text F1 and leads all evaluated baselines on multimodal safety, with policy set at inference time.
NOOA: NVIDIA's Object-Oriented Agent Framework Explained
NVIDIA open-sources NOOA, a Python framework that collapses prompt templates, tool schemas, and workflow graphs into one class—with 82.2% on SWE-bench Verified.
TencentDB Agent Memory v2.0: A Team-Level Memory Hub for AI Coding Agents
Tencent Cloud open-sources TencentDB Agent Memory v2.0: MIT-licensed, self-hosted, four-asset memory governance for multi-agent coding teams.
Anthropic and Industry Partners Launch Akrites for AI-Era Open Source Security
Akrites brings major AI, cloud, finance, and security organizations together to coordinate vulnerability fixes before disclosure.
Chandra OCR 2 Shows How Fast Open-Source Document AI Is Catching Up
Datalab's Chandra OCR 2 is pushing open-source OCR past legacy parsers with stronger layout, math, table, and multilingual performance.
GLM-5.2 Raises the Bar for Text-Only Open-Weights LLMs
Z.ai's GLM-5.2 arrives as a 753B-parameter open-weights text model with a 1M-token context window, strong benchmark results, and aggressive API pricing.
Harness-1 Shows Smaller Open Models Can Beat Frontier AI at Search
Harness-1 is a 20B open-source search agent that beats GPT-5.4 on recall by moving search memory out of the model and into a structured environment.
Best Small Language Models on Hugging Face Right Now
A practical look at compact open-weight language models that balance capability, latency, memory use, and local deployment flexibility.
Linus Torvalds Warns AI Bug Reports Are Overloading Linux Security Maintainers
Linus Torvalds says duplicate AI-generated bug reports are making Linux security triage harder, not easier, unless reporters add patches and context.
OpenClaw Alternatives: Hermes, NanoBot, ZeroClaw, and PicoClaw Compared
A practical comparison of four OpenClaw alternatives for autonomous workflows, lightweight automation, persistent assistants, and low-resource deployments.
Moonshot AI Debuts Kimi K2.6: The 1-Trillion Parameter Swarm Model
Moonshot AI releases its most powerful model yet, Kimi K2.6, featuring a massive agent swarm architecture designed for long-horizon coding and complex orchestration.
Meta Expected to Launch Llama 4: Open Source Dominance Imminent
Industry insiders report that Meta's highly anticipated Llama 4 base models will launch this quarter, challenging API monopolies.
Z.ai Disrupts Open Source with GLM-5.1 Autonomous Model
The newly released GLM-5.1 breaks open-source benchmarks by sustaining 8-hour autonomous engineering sessions.