
Tool Calling
5 pieces on Tool Calling, including 2 step-by-step guides.
Guides
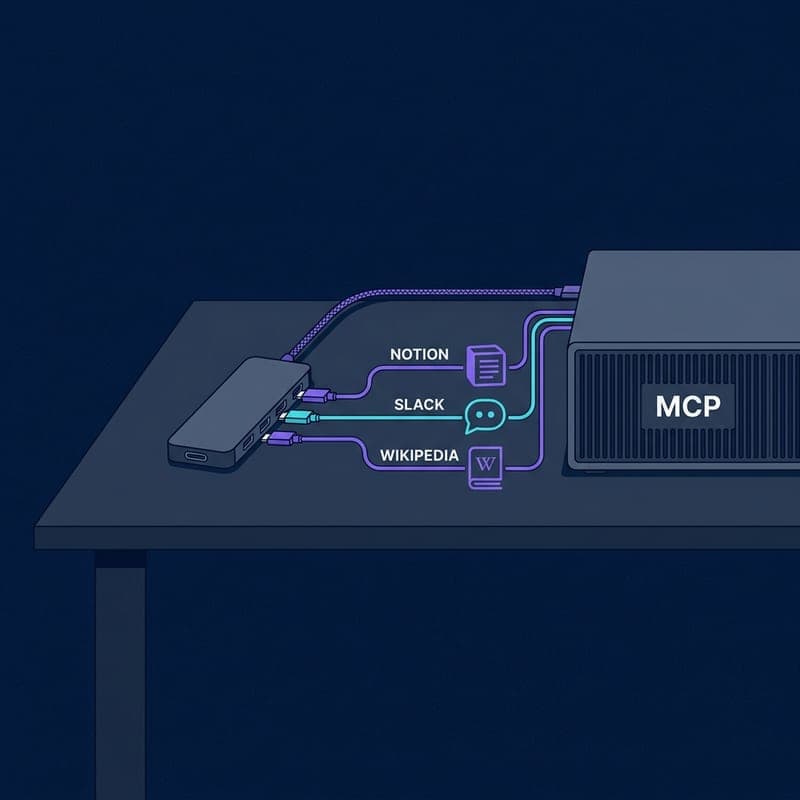
Expose LlamaIndex Tool Specs as an MCP Server with fastmcp
Turn any LlamaIndex LlamaHub tool spec into a compliant MCP server in ~50 lines using fastmcp and NotionToolSpec.
Read more →
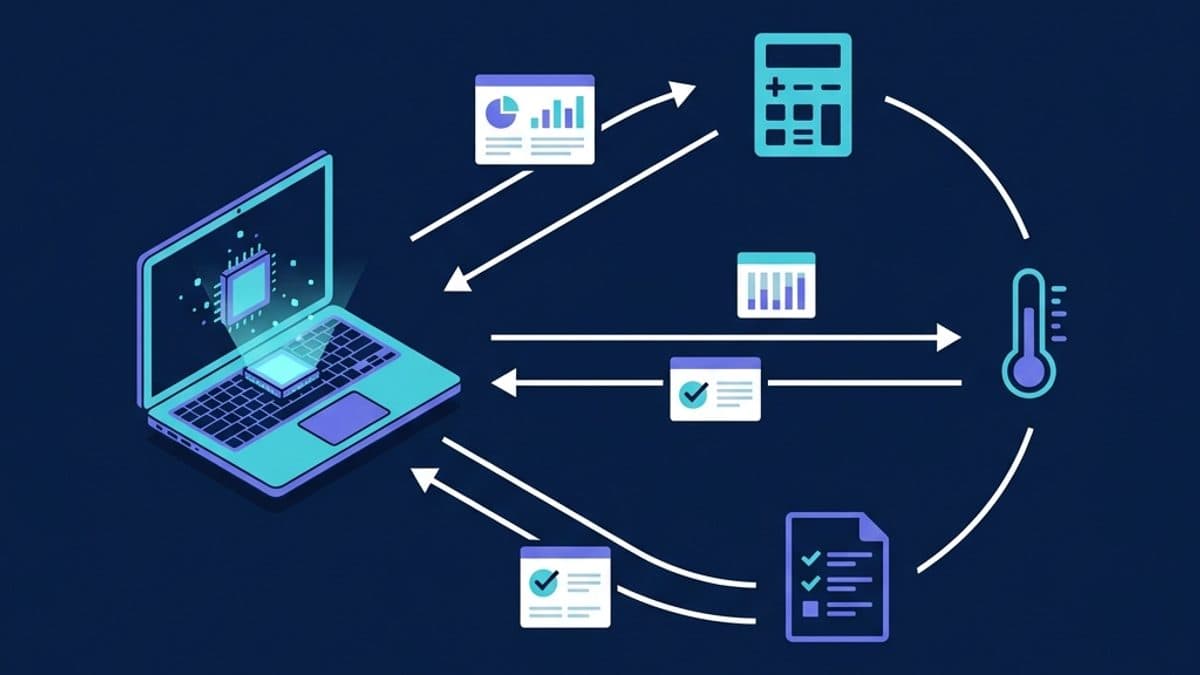
Build a Tool-Calling Agent with a Local Small Model and Ollama (2026)
Give a local small language model tools with Ollama's Python library: function tools, multi-tool streaming with thinking, and validated JSON output.
Read more →
News & Analysis
Fine-Tuning Qwen3-0.6B for Tool Calling with XYZ-Aquila-SFT
A reproducible SFT pipeline streams 400 XYZ-Aquila-SFT trajectories, bypasses apply_chat_template to preserve reasoning blocks, and fine-tunes Qwen3-0.6B with LoRA.
Read more →
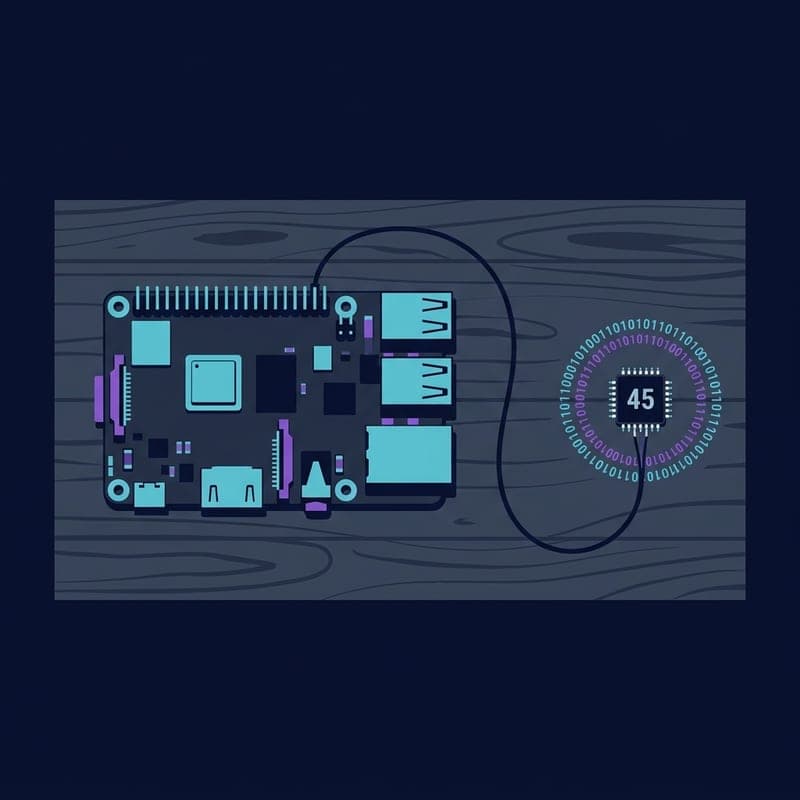
Needle 2: 45M-Parameter Tool-Calling Model in a 14MB Binary
Cactus Compute's Needle 2 runs a full inference session in 28MB of RAM, hits 500 tokens/sec on a Raspberry Pi 5, and needs no GPU.
Read more →
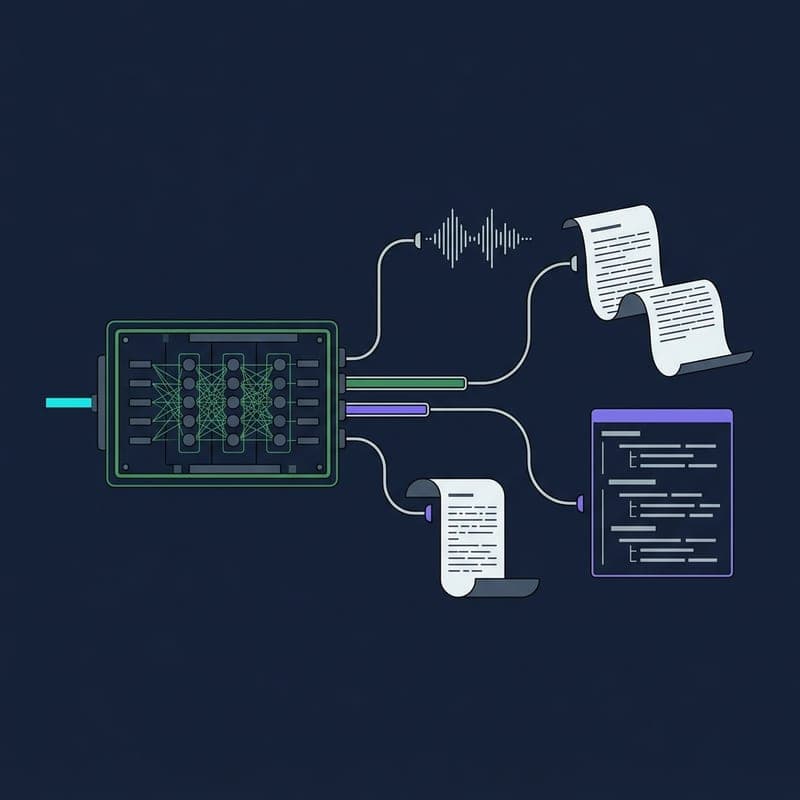
NVIDIA VoiceChat 11B: Open Full-Duplex Speech Model with 448 ms Latency
NVIDIA's NemotronLabs VoiceChat 11B unifies ASR, LLM, and TTS into one 11B model with 448 ms turn-taking and live tool calling.
Read more →