
In this article
- Prerequisites
- Step 1: Install dependencies and set API keys
- Step 2: Create a local vector index
- Step 3: Route queries between vectorstore and web search
- Step 4: Grade retrieved documents
- Step 5: Generate with RAG
- Step 6: Grade hallucinations and answer usefulness
- Step 7: Rewrite queries and add web search fallback
- Step 8: Define graph state, nodes, and edges
- Step 9: Compile and run the graph
- What to watch out for
Most retrieval-augmented generation demos stop at “retrieve, stuff, answer.” Production queries do not cooperate with that shape. A question about a recent event should skip a static vector index; a query that retrieves weakly related chunks should trigger a rewrite instead of a confident, unsupported answer; an answer that contradicts the retrieved facts should loop back for correction. LangGraph’s adaptive RAG notebook turns those choices into an explicit state machine that routes, grades, rewrites, regenerates, and falls back to web search. This guide adapts that tested notebook into a fully local pipeline: Ollama runs Mistral, Nomic supplies local embeddings, Chroma stores the index, and Tavily provides the web fallback.
Attribution: this guide is adapted from LangGraph’s langgraph_adaptive_rag_local.ipynb in the langchain-ai/langgraph repository, used under its MIT licence. The code blocks are reproduced from that notebook and left unmodified.
This workflow is aimed at ML engineers and application builders who already run RAG over a curated corpus and want it to fail gracefully. It reduces per-token API spend because the generator and most graders run locally, but it is not free: you still need Tavily and Nomic accounts, a machine that can hold the embedding model plus the LLM, and patience for several LLM calls per query. The source notebook does not report baseline timings. Because the graph can invoke the local LLM for routing, grading each document, generation, hallucination checking, answer checking, and rewriting, latency multiples across a full run.
What this guide adds beyond the notebook is the operational layer: a component matrix that separates five easily confused decision steps, and explicit failure modes that appear when you move beyond the included sample questions.
Prerequisites
The notebook assumes a working Python environment and does not pin exact package versions beyond installing the latest with pip install -U. You need:
- Ollama installed locally, with
ollama pull mistral. - NOMIC_API_KEY and TAVILY_API_KEY. The notebook reads both from environment variables using
getpass. - Optional but useful: LangSmith for tracing graph runs and debugging repeated loops.
The source code does not pin benchmark hardware. Mistral is the local model named in the notebook, but local CPU-only inference is still much slower than a hosted API. Do not expect interactive latency on a thin laptop. If you want to explore heavier local open models, our coverage of Meta Muse Spark running on two Mac Studios is a useful reference for the compute envelope.
Step 1: Install dependencies and set API keys
Install the package set exactly as the notebook does. Because this uses -U, the resolver will pull current versions; if you need reproducible runs, freeze a lockfile after this install.
%capture --no-stderr
%pip install -U langchain-nomic langchain_community tiktoken langchainhub chromadb langchain langgraph tavily-python nomic[local]
The environment block avoids writing secrets into the notebook. The helper only prompts when a variable is missing, so existing shell variables are left untouched.
import getpass
import os


def _set_env(var: str):
    if not os.environ.get(var):
        os.environ[var] = getpass.getpass(f"{var}: ")


_set_env("TAVILY_API_KEY")
_set_env("NOMIC_API_KEY")
Step 2: Create a local vector index
The notebook declares the Ollama model once so every ChatOllama instance shares it. The default is mistral; keep it unless you have already pulled another model and are prepared for different grader behaviour.
# Ollama model name
local_llm = "mistral"
Three Lilian Weng blog posts are loaded, split into 250-token chunks with no overlap, embedded with Nomic’s local nomic-embed-text-v1.5, and stored in a local Chroma collection. The inference_mode="local" argument tells Nomic to run the embedding model on your machine; the first run may still need network access to obtain the weights.
from langchain.text_splitter import RecursiveCharacterTextSplitter
from langchain_community.document_loaders import WebBaseLoader
from langchain_community.vectorstores import Chroma
from langchain_nomic.embeddings import NomicEmbeddings

urls = [
    "https://lilianweng.github.io/posts/2023-06-23-agent/",
    "https://lilianweng.github.io/posts/2023-03-15-prompt-engineering/",
    "https://lilianweng.github.io/posts/2023-10-25-adv-attack-llm/",
]

docs = [WebBaseLoader(url).load() for url in urls]
docs_list = [item for sublist in docs for item in sublist]

text_splitter = RecursiveCharacterTextSplitter.from_tiktoken_encoder(
    chunk_size=250, chunk_overlap=0
)
doc_splits = text_splitter.split_documents(docs_list)

# Add to vectorDB
vectorstore = Chroma.from_documents(
    documents=doc_splits,
    collection_name="rag-chroma",
    embedding=NomicEmbeddings(model="nomic-embed-text-v1.5", inference_mode="local"),
)
retriever = vectorstore.as_retriever()
Step 3: Route queries between vectorstore and web search
The router collapses query analysis into a binary JSON decision. It sends questions about LLM agents, prompt engineering, and adversarial attacks to the vectorstore; everything else goes to web search. The prompt intentionally avoids strict keyword matching, so a question like “llm agent memory” still routes correctly. The format="json" parameter asks Ollama to emit structured output, and JsonOutputParser parses it.
### Router

from langchain.prompts import PromptTemplate
from langchain_community.chat_models import ChatOllama
from langchain_core.output_parsers import JsonOutputParser

# LLM
llm = ChatOllama(model=local_llm, format="json", temperature=0)

prompt = PromptTemplate(
    template="""You are an expert at routing a user question to a vectorstore or web search. \n
    Use the vectorstore for questions on LLM  agents, prompt engineering, and adversarial attacks. \n
    You do not need to be stringent with the keywords in the question related to these topics. \n
    Otherwise, use web-search. Give a binary choice 'web_search' or 'vectorstore' based on the question. \n
    Return the a JSON with a single key 'datasource' and no premable or explanation. \n
    Question to route: {question}""",
    input_variables=["question"],
)

question_router = prompt | llm | JsonOutputParser()
question = "llm agent memory"
docs = retriever.get_relevant_documents(question)
doc_txt = docs[1].page_content
print(question_router.invoke({"question": question}))
Step 4: Grade retrieved documents
Before generation, each retrieved document must pass a relevance gate. This grader returns a binary yes or no in JSON. The prompt is deliberately lenient: it only needs to filter out clearly erroneous retrievals, not perform fine-grained semantic ranking.
### Retrieval Grader

from langchain.prompts import PromptTemplate
from langchain_community.chat_models import ChatOllama
from langchain_core.output_parsers import JsonOutputParser

# LLM
llm = ChatOllama(model=local_llm, format="json", temperature=0)

prompt = PromptTemplate(
    template="""You are a grader assessing relevance of a retrieved document to a user question. \n
    Here is the retrieved document: \n\n {document} \n\n
    Here is the user question: {question} \n
    If the document contains keywords related to the user question, grade it as relevant. \n
    It does not need to be a stringent test. The goal is to filter out erroneous retrievals. \n
    Give a binary score 'yes' or 'no' score to indicate whether the document is relevant to the question. \n
    Provide the binary score as a JSON with a single key 'score' and no premable or explanation.""",
    input_variables=["question", "document"],
)

retrieval_grader = prompt | llm | JsonOutputParser()
question = "agent memory"
docs = retriever.get_relevant_documents(question)
doc_txt = docs[1].page_content
print(retrieval_grader.invoke({"question": question, "document": doc_txt}))
Step 5: Generate with RAG
Generation uses LangChain Hub’s rlm/rag-prompt and a plain string output parser. The format_docs helper joins page contents, although the cell below invokes the chain with the raw docs list. In the graph, this same rag_chain is reused for both vectorstore and web-search paths.
### Generate

from langchain import hub
from langchain_community.chat_models import ChatOllama
from langchain_core.output_parsers import StrOutputParser

# Prompt
prompt = hub.pull("rlm/rag-prompt")

# LLM
llm = ChatOllama(model=local_llm, temperature=0)


# Post-processing
def format_docs(docs):
    return "\n\n".join(doc.page_content for doc in docs)


# Chain
rag_chain = prompt | llm | StrOutputParser()

# Run
question = "agent memory"
generation = rag_chain.invoke({"context": docs, "question": question})
print(generation)
Step 6: Grade hallucinations and answer usefulness
The graph does not trust the first generation. A hallucination grader checks whether the answer is supported by the documents, returning yes or no in JSON. A second answer grader checks whether the answer actually resolves the question. Together they decide whether the run can finish, regenerate, or rewrite.
### Hallucination Grader

# LLM
llm = ChatOllama(model=local_llm, format="json", temperature=0)

# Prompt
prompt = PromptTemplate(
    template="""You are a grader assessing whether an answer is grounded in / supported by a set of facts. \n
    Here are the facts:
    \n ------- \n
    {documents}
    \n ------- \n
    Here is the answer: {generation}
    Give a binary score 'yes' or 'no' score to indicate whether the answer is grounded in / supported by a set of facts. \n
    Provide the binary score as a JSON with a single key 'score' and no preamble or explanation.""",
    input_variables=["generation", "documents"],
)

hallucination_grader = prompt | llm | JsonOutputParser()
hallucination_grader.invoke({"documents": docs, "generation": generation})
### Answer Grader

# LLM
llm = ChatOllama(model=local_llm, format="json", temperature=0)

# Prompt
prompt = PromptTemplate(
    template="""You are a grader assessing whether an answer is useful to resolve a question. \n
    Here is the answer:
    \n ------- \n
    {generation}
    \n ------- \n
    Here is the question: {question}
    Give a binary score 'yes' or 'no' to indicate whether the answer is useful to resolve a question. \n
    Provide the binary score as a JSON with a single key 'score' and no preamble or explanation.""",
    input_variables=["generation", "question"],
)

answer_grader = prompt | llm | JsonOutputParser()
answer_grader.invoke({"question": question, "generation": generation})
Step 7: Rewrite queries and add web search fallback
If every retrieved document is filtered out, the graph rewrites the query for better vectorstore retrieval and loops back. The rewrite prompt asks for an improved version with no preamble, returning a plain string. The web search tool uses Tavily to fetch the top three results, which are then fed into the generation node as synthetic context.
### Question Re-writer

# LLM
llm = ChatOllama(model=local_llm, temperature=0)

# Prompt
re_write_prompt = PromptTemplate(
    template="""You a question re-writer that converts an input question to a better version that is optimized \n
     for vectorstore retrieval. Look at the initial and formulate an improved question. \n
     Here is the initial question: \n\n {question}. Improved question with no preamble: \n """,
    input_variables=["generation", "question"],
)

question_rewriter = re_write_prompt | llm | StrOutputParser()
question_rewriter.invoke({"question": question})
### Search

from langchain_community.tools.tavily_search import TavilySearchResults

web_search_tool = TavilySearchResults(k=3)
At this point the pipeline has five decision components. Their roles and failure modes are easy to confuse, so the matrix below separates them before the graph ties them together.
| Component | What it decides | Inputs | Output | Graph consequence |
|---|---|---|---|---|
question_router |
Index or live web? | User question | datasource |
Routes to retrieve or web_search |
retrieval_grader |
Is this chunk relevant? | Question + one document | score |
Filters unrelated chunks before generation |
hallucination_grader |
Is the answer supported? | Generation + documents | score |
Regenerates if unsupported |
answer_grader |
Does the answer help the user? | Generation + question | score |
Rewrites query if not useful |
question_rewriter |
Can a better query retrieve better chunks? | Question | Plain string | Loops back to retrieve |
Step 8: Define graph state, nodes, and edges
LangGraph state is a simple TypedDict with three fields: the question, the generated answer, and the documents in play. Different nodes update different pieces while preserving the rest.
from typing import List

from typing_extensions import TypedDict


class GraphState(TypedDict):
    """
    Represents the state of our graph.

    Attributes:
        question: question
        generation: LLM generation
        documents: list of documents
    """

    question: str
    generation: str
    documents: List[str]
The nodes wrap the components from Steps 3–7. grade_documents scores every retrieved document and keeps only those graded yes. web_search packages Tavily results into a single Document. The conditional edges then control movement: routing from start, deciding whether to generate after grading, and deciding whether to finish, regenerate, or transform after generation.
### Nodes

from langchain.schema import Document


def retrieve(state):
    """
    Retrieve documents

    Args:
        state (dict): The current graph state

    Returns:
        state (dict): New key added to state, documents, that contains retrieved documents
    """
    print("---RETRIEVE---")
    question = state["question"]

    # Retrieval
    documents = retriever.get_relevant_documents(question)
    return {"documents": documents, "question": question}


def generate(state):
    """
    Generate answer

    Args:
        state (dict): The current graph state

    Returns:
        state (dict): New key added to state, generation, that contains LLM generation
    """
    print("---GENERATE---")
    question = state["question"]
    documents = state["documents"]

    # RAG generation
    generation = rag_chain.invoke({"context": documents, "question": question})
    return {"documents": documents, "question": question, "generation": generation}


def grade_documents(state):
    """
    Determines whether the retrieved documents are relevant to the question.

    Args:
        state (dict): The current graph state

    Returns:
        state (dict): Updates documents key with only filtered relevant documents
    """

    print("---CHECK DOCUMENT RELEVANCE TO QUESTION---")
    question = state["question"]
    documents = state["documents"]

    # Score each doc
    filtered_docs = []
    for d in documents:
        score = retrieval_grader.invoke(
            {"question": question, "document": d.page_content}
        )
        grade = score["score"]
        if grade == "yes":
            print("---GRADE: DOCUMENT RELEVANT---")
            filtered_docs.append(d)
        else:
            print("---GRADE: DOCUMENT NOT RELEVANT---")
            continue
    return {"documents": filtered_docs, "question": question}


def transform_query(state):
    """
    Transform the query to produce a better question.

    Args:
        state (dict): The current graph state

    Returns:
        state (dict): Updates question key with a re-phrased question
    """

    print("---TRANSFORM QUERY---")
    question = state["question"]
    documents = state["documents"]

    # Re-write question
    better_question = question_rewriter.invoke({"question": question})
    return {"documents": documents, "question": better_question}


def web_search(state):
    """
    Web search based on the re-phrased question.

    Args:
        state (dict): The current graph state

    Returns:
        state (dict): Updates documents key with appended web results
    """

    print("---WEB SEARCH---")
    question = state["question"]

    # Web search
    docs = web_search_tool.invoke({"query": question})
    web_results = "\n".join([d["content"] for d in docs])
    web_results = Document(page_content=web_results)

    return {"documents": web_results, "question": question}


### Edges ###


def route_question(state):
    """
    Route question to web search or RAG.

    Args:
        state (dict): The current graph state

    Returns:
        str: Next node to call
    """

    print("---ROUTE QUESTION---")
    question = state["question"]
    print(question)
    source = question_router.invoke({"question": question})
    print(source)
    print(source["datasource"])
    if source["datasource"] == "web_search":
        print("---ROUTE QUESTION TO WEB SEARCH---")
        return "web_search"
    elif source["datasource"] == "vectorstore":
        print("---ROUTE QUESTION TO RAG---")
        return "vectorstore"


def decide_to_generate(state):
    """
    Determines whether to generate an answer, or re-generate a question.

    Args:
        state (dict): The current graph state

    Returns:
        str: Binary decision for next node to call
    """

    print("---ASSESS GRADED DOCUMENTS---")
    state["question"]
    filtered_documents = state["documents"]

    if not filtered_documents:
        # All documents have been filtered check_relevance
        # We will re-generate a new query
        print(
            "---DECISION: ALL DOCUMENTS ARE NOT RELEVANT TO QUESTION, TRANSFORM QUERY---"
        )
        return "transform_query"
    else:
        # We have relevant documents, so generate answer
        print("---DECISION: GENERATE---")
        return "generate"


def grade_generation_v_documents_and_question(state):
    """
    Determines whether the generation is grounded in the document and answers question.

    Args:
        state (dict): The current graph state

    Returns:
        str: Decision for next node to call
    """

    print("---CHECK HALLUCINATIONS---")
    question = state["question"]
    documents = state["documents"]
    generation = state["generation"]

    score = hallucination_grader.invoke(
        {"documents": documents, "generation": generation}
    )
    grade = score["score"]

    # Check hallucination
    if grade == "yes":
        print("---DECISION: GENERATION IS GROUNDED IN DOCUMENTS---")
        # Check question-answering
        print("---GRADE GENERATION vs QUESTION---")
        score = answer_grader.invoke({"question": question, "generation": generation})
        grade = score["score"]
        if grade == "yes":
            print("---DECISION: GENERATION ADDRESSES QUESTION---")
            return "useful"
        else:
            print("---DECISION: GENERATION DOES NOT ADDRESS QUESTION---")
            return "not useful"
    else:
        pprint("---DECISION: GENERATION IS NOT GROUNDED IN DOCUMENTS, RE-TRY---")
        return "not supported"
Step 9: Compile and run the graph
The workflow wires all conditional outcomes into concrete paths. A start routes to web search or retrieve; web search goes straight to generation; retrieval goes through document grading; transform loops back to retrieval; generation exits only when the answer is grounded and useful.
from langgraph.graph import END, StateGraph, START

workflow = StateGraph(GraphState)

# Define the nodes
workflow.add_node("web_search", web_search)  # web search
workflow.add_node("retrieve", retrieve)  # retrieve
workflow.add_node("grade_documents", grade_documents)  # grade documents
workflow.add_node("generate", generate)  # generate
workflow.add_node("transform_query", transform_query)  # transform_query

# Build graph
workflow.add_conditional_edges(
    START,
    route_question,
    {
        "web_search": "web_search",
        "vectorstore": "retrieve",
    },
)
workflow.add_edge("web_search", "generate")
workflow.add_edge("retrieve", "grade_documents")
workflow.add_conditional_edges(
    "grade_documents",
    decide_to_generate,
    {
        "transform_query": "transform_query",
        "generate": "generate",
    },
)
workflow.add_edge("transform_query", "retrieve")
workflow.add_conditional_edges(
    "generate",
    grade_generation_v_documents_and_question,
    {
        "not supported": "generate",
        "useful": END,
        "not useful": "transform_query",
    },
)

# Compile
app = workflow.compile()
The test question asks about AlphaCodium, which is not part of the indexed blog posts. It should route to web search, package Tavily results, generate an answer, and pass both quality gates.
from pprint import pprint

# Run
inputs = {"question": "What is the AlphaCodium paper about?"}
for output in app.stream(inputs):
    for key, value in output.items():
        # Node
        pprint(f"Node '{key}':")
        # Optional: print full state at each node
        # pprint.pprint(value["keys"], indent=2, width=80, depth=None)
    pprint("\n---\n")

# Final generation
pprint(value["generation"])
What to watch out for
The notebook is a teaching state machine, not a hardened production service. Several failure modes are easy to hit once you move beyond the included sample questions.
The retriever API has changed. The notebook calls retriever.get_relevant_documents(...). Current LangChain versions increasingly expose invoke and ainvoke instead. If you install the latest packages exactly as this guide does, pin or adapt the call outside the reproduced blocks, or you may encounter deprecation and removal errors.
format="json" is not a guarantee. Ollama’s JSON mode reduces preamble but does not eliminate malformed output. A single unparsable router or grader response aborts the graph with no recovery. In a real deployment, wrap JsonOutputParser with retries, schema validation, or a repair pass.
The web search node returns a Document, not a list. GraphState declares documents: List[str], but web_search returns {"documents": web_results, ...} where web_results is a single Document. Later graders and the generator may stringify that object into page_content='...' metadata=..., which degrades both grounding checks and generated answers. Normalize web results into a list of documents before passing them on.
There is no loop limit. If the question rewriter cannot produce a query that retrieves relevant docs, the graph cycles endlessly between transform_query, retrieve, and grade_documents. LangGraph will happily run that loop until you stop it or exceed resources.
Document grading is one LLM call per chunk. With 250-token chunks from only three blog posts, that is manageable. With thousands of chunks, latency and local CPU cost grow linearly before generation even starts. Batch grading or use a smaller pre-filter.
The router is hard-coded to three topics. It sends “LLM agents, prompt engineering, adversarial attacks” to the vectorstore and everything else to web search. If you index a different corpus and forget to update this prompt, every query will bypass your index.
pprint appears before an import. The graph cell calls pprint in the unsupported-answer branch, but from pprint import pprint occurs later in the run cell. This only fails if that branch executes before the import is available; add the import at the top of the graph cell in any fork.
Local embeddings may need a first-run download. NomicEmbeddings(..., inference_mode="local") still requires the model weights. Run once with network access before assuming an offline deployment.
Tavily is metered. Every web fallback consumes API credits, and k=3 can still return long snippets that expand the context passed to the generator. Monitor rate limits and total token usage.
Where to go next: replace the hard-coded router with a scorer that can return “none” for no-retrieval, add a maximum iteration count, and trace all state transitions in LangSmith. If you are weighing local hardware for larger open models, see our coverage of Meta Muse Spark running on two Mac Studios. LangGraph’s consolidated documentation is the natural next stop for current APIs and multi-agent extensions.
Frequently asked questions
How do I run LangGraph adaptive RAG locally?
Install the notebook dependencies with pip install -U langchain-nomic langchain_community tiktoken langchainhub chromadb langchain langgraph tavily-python nomic[local], then set TAVILY_API_KEY and NOMIC_API_KEY. Pull the Ollama mistral model and run the notebook cells in order. The graph routes between a local Chroma vectorstore built from three Lilian Weng posts and a Tavily web search fallback.
Why does adaptive RAG use so many LLM calls?
The graph calls ChatOllama separately to route the question, grade each retrieved document, generate an answer, check hallucinations, check answer usefulness, and optionally rewrite the query. This adds robustness because each step can correct the previous one, but it multiples latency. The notebook does not include baseline timings, so local speed depends on the model and hardware.
Why can Ollama JSON mode still break the graph?
The notebook sets ChatOllama format to json and parses outputs with JsonOutputParser, but Ollama can still return malformed JSON. There is no retry, schema validation, or repair pass in the reproduced notebook, so one bad router or grader response aborts the graph. A production version should wrap the parser with error handling.
How do I stop the graph looping forever on irrelevant documents?
If grade_documents filters out every document, decide_to_generate routes to transform_query, which rewrites the question and returns to retrieve. The source graph has no maximum loop count or no-answer terminal state, so it will keep cycling until interrupted or resources run out. Add a bounded rewrite count or a fallback answer before deploying the workflow.
Does the web search node return the same document structure as the vectorstore?
No. The retrieve node returns a list of Document objects, but the web_search node joins Tavily result content into a single Document and returns that one object in the documents field. Later graders may stringify that different object unexpectedly, which can weaken grounding checks and generated answers. Normalize web results into a list of documents before generation.
Can I use a different local model instead of Mistral?
Yes. The notebook sets local_llm to mistral and reuses that variable in every ChatOllama instance. You can change it to another model already pulled in Ollama; routing, grading, and rewrite behavior may change because the prompts depend on the replacement model following the JSON and instruction format.
Related Guides
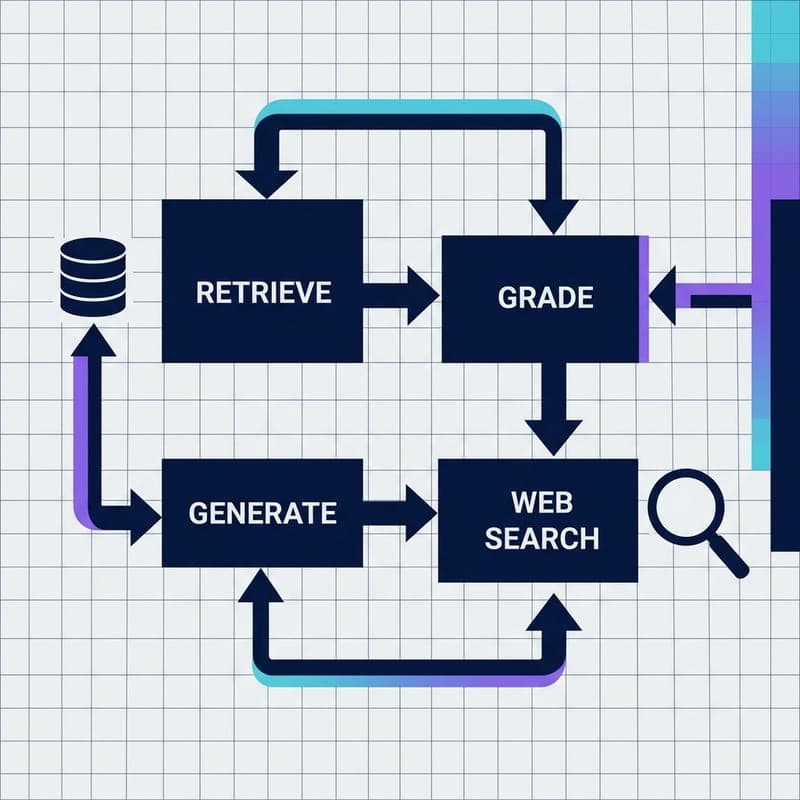
Build a Self-Correcting RAG Agent with LangGraph and Milvus
Wire adaptive routing, corrective RAG, and self-RAG into a stateful LangGraph agent backed by Milvus Lite — no OpenAI key required.
Build Persistent Agent Working Memory with MongoDB and Tavily
Store, retrieve, and grow agent memory across sessions using MongoDB Atlas Vector Search and Tavily hybrid RAG with save_foreign.
The Complete Developer Guide to Running LLMs Locally: From Ollama to Production
Everything you need to run LLMs on your own hardware in 2026: VRAM sizing, model formats, an 8-tool comparison table, a full local RAG pipeline, and Docker production deployment with GPU passthrough and Nginx auth.