
RAG
40 pieces on RAG, including 21 step-by-step guides.
Guides
Build a Hybrid Sparse-Dense RAG Search Pipeline in Milvus
Configure Milvus with BGE-M3 dense and sparse embeddings, dual indices, and Reciprocal Rank Fusion for resilient lexical and semantic retrieval.
Generate Synthetic RAG Test Sets With Ragas
Build, save and reuse a Ragas knowledge graph to generate single-hop and multi-hop evaluation queries from Markdown documents.
Build an Agentic RAG System with smolagents and ChromaDB
Use smolagents CodeAgent to run multi-step retrieval over a ChromaDB vector store, letting the agent plan its own search strategy.
Build a Routed RAG Chatbot with LlamaIndex and Chainlit
Dispatch queries across independent retrieval pipelines using LlamaIndex QueryFlow, Chainlit, and NVIDIA NIM endpoints.
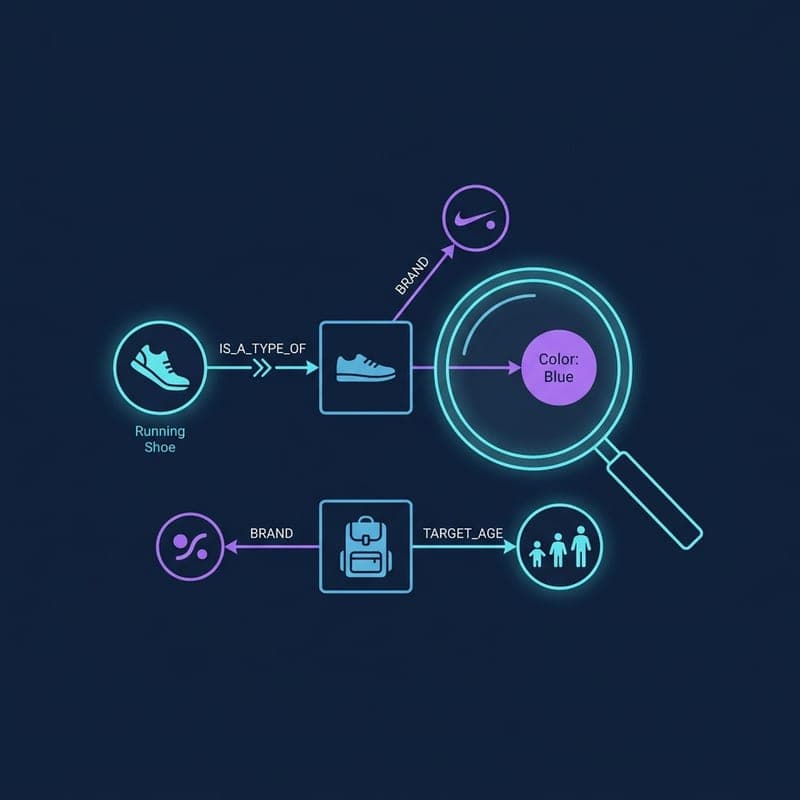
Graph RAG with Neo4j and OpenAI: Build a Product Search Pipeline
Combine Neo4j property graphs, GPT-4o entity extraction, and cosine similarity to build a multi-strategy product retrieval pipeline.
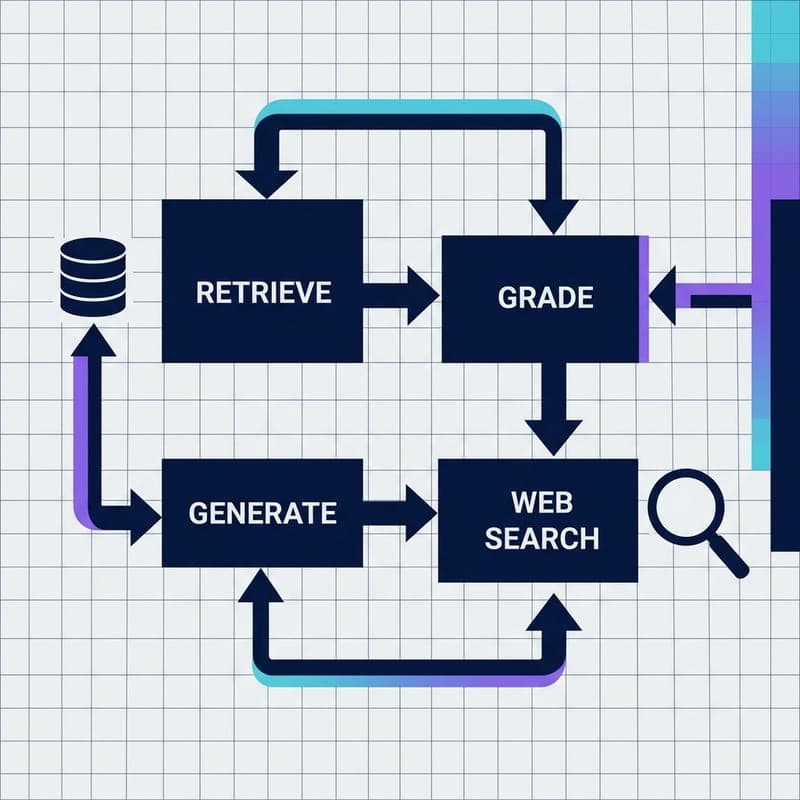
Build a Self-Correcting RAG Agent with LangGraph and Milvus
Wire adaptive routing, corrective RAG, and self-RAG into a stateful LangGraph agent backed by Milvus Lite — no OpenAI key required.
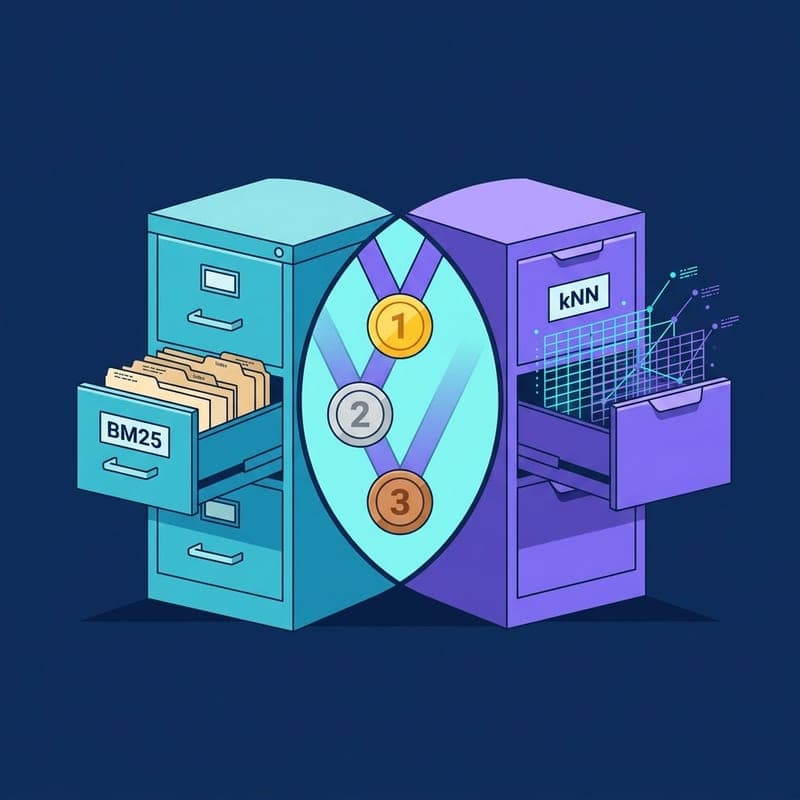
Hybrid Search with RRF in Elasticsearch: A Complete Guide
Combine BM25 and kNN vector search using Reciprocal Rank Fusion in Elasticsearch to build a production-ready RAG retriever in Python.
Build Persistent Agent Working Memory with MongoDB and Tavily
Store, retrieve, and grow agent memory across sessions using MongoDB Atlas Vector Search and Tavily hybrid RAG with save_foreign.
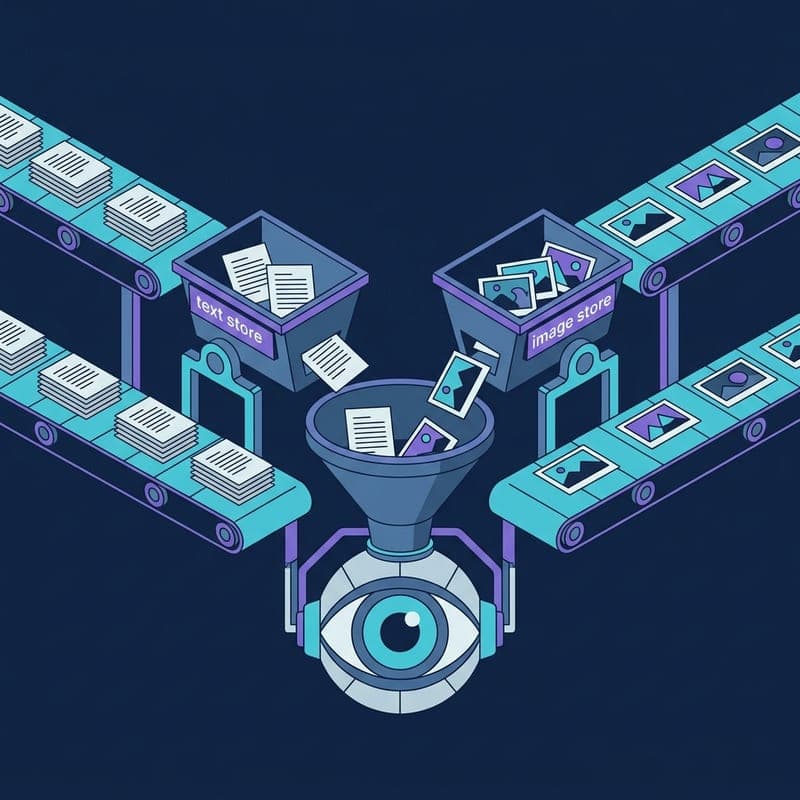
Build a Multi-Modal RAG Pipeline with LlamaIndex and Qdrant
Index text and images into separate Qdrant stores, retrieve across both modalities, and answer queries with GPT-4 Vision using LlamaIndex.
The Complete Developer Guide to Running LLMs Locally: From Ollama to Production
Everything you need to run LLMs on your own hardware in 2026: VRAM sizing, model formats, an 8-tool comparison table, a full local RAG pipeline, and Docker production deployment with GPU passthrough and Nginx auth.
How to Run DeepSeek R1 Locally with Ollama: Full Setup Guide
Install DeepSeek R1 locally using Ollama in under 5 minutes. Covers model variant selection from 1.5B to 671B, visible chain-of-thought reasoning, REST API usage, Python integration, and building a simple RAG application.
Mastering Advanced RAG Evaluation: From Basic Metrics to LLM-as-a-Judge
Learn how to systematically evaluate Retrieval-Augmented Generation (RAG) pipelines using the RAG Triad, Ragas, and LLM-as-a-Judge techniques.
Beyond Prompt Engineering: Deep-Dive RAG for Intent Detection & Slot Filling in AI Agents
Stop relying on massive, static context prompts. Learn how to combine Retrieval-Augmented Generation (RAG), vector search (FAISS), and history compaction to achieve scalable intent detection and slot filling.
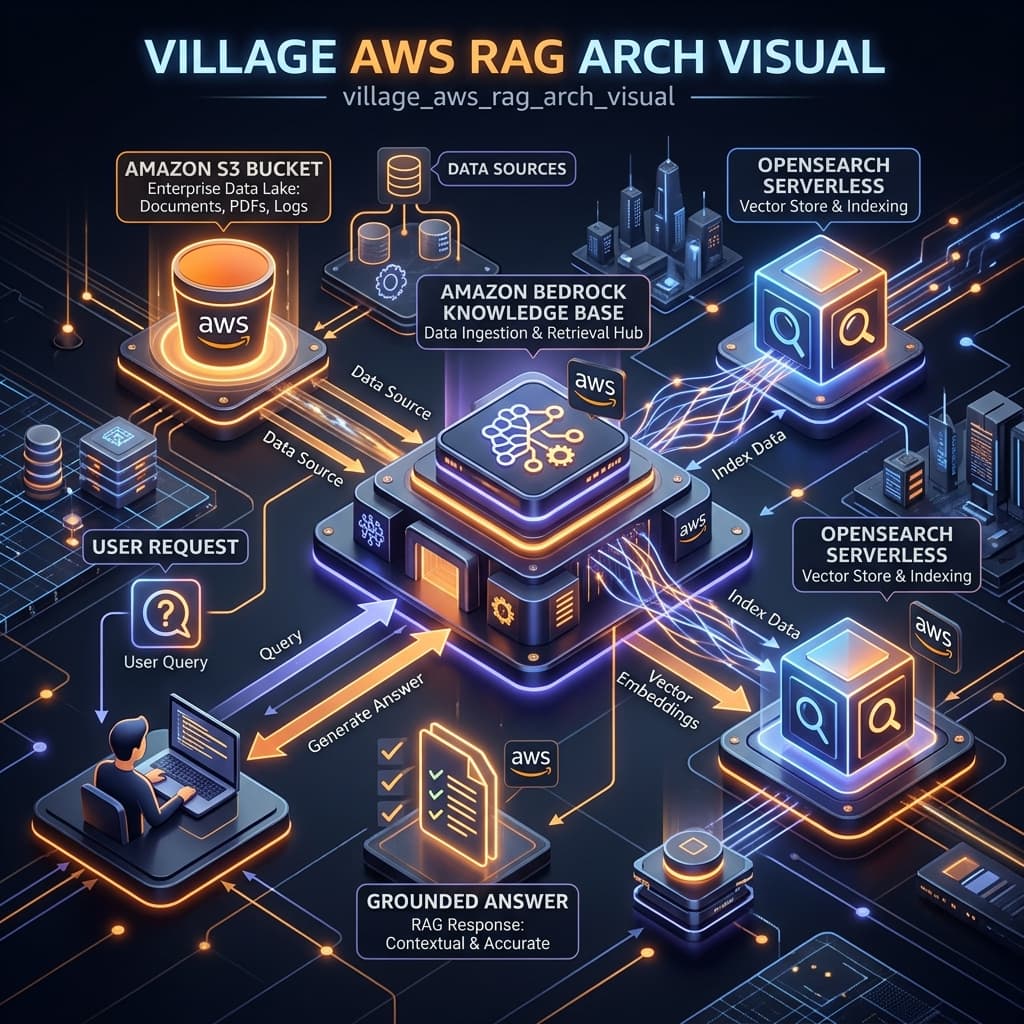
Building a Production RAG Pipeline with Bedrock and OpenSearch Serverless
Everyone has shipped a RAG demo. Shipping one that survives real traffic, security audits, and finance reviews requires a different architecture. Explore the enterprise-grade RAG stack on AWS.

Secure RAG on Google Cloud with RAG Engine and Gemini (2026)
Build RAG on Google Cloud with RAG Engine and Gemini, then lock it down: IAM-scoped corpora, VPC Service Controls, CMEK, and what is not supported.
Learning to Rank: The Hidden Layer Powering Modern RAG
Your RAG pipeline is only as good as your ranker. Explore the technical depths of Learning to Rank (LTR), from LambdaMART's 'Physics Trick' to the Cross-Encoder tradeoff that determines production success.
Designing a Production-Grade RAG Architecture
Large Language Models are powerful—but infamously unreliable when forced to guess. Learn how to build a production-grade RAG architecture that eliminates hallucinations through hybrid search, reranking, and structured ingestion.
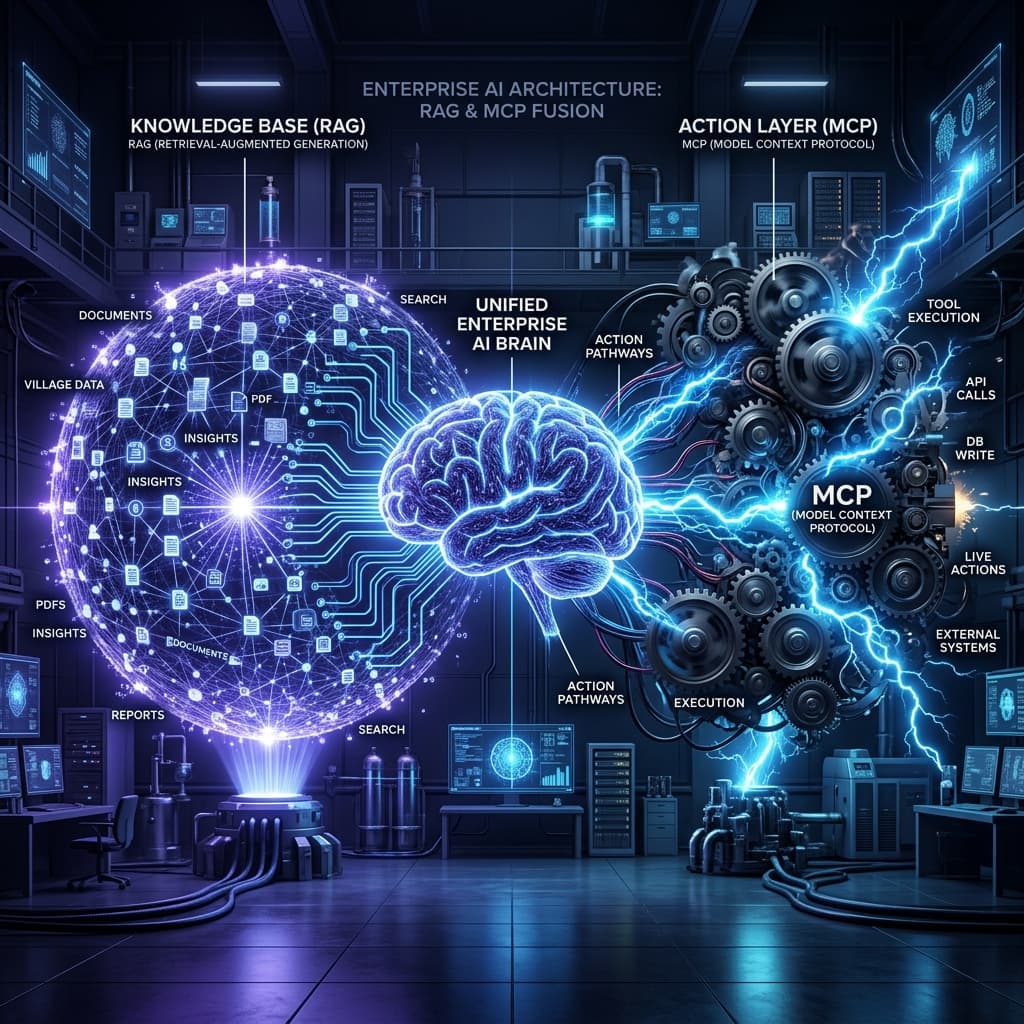
RAG vs MCP in 2026: What Each Solves and How They Fit Together
RAG is a technique for grounding answers in your data; MCP is a protocol for connecting models to tools and data. Build an MCP server and see where RAG fits.
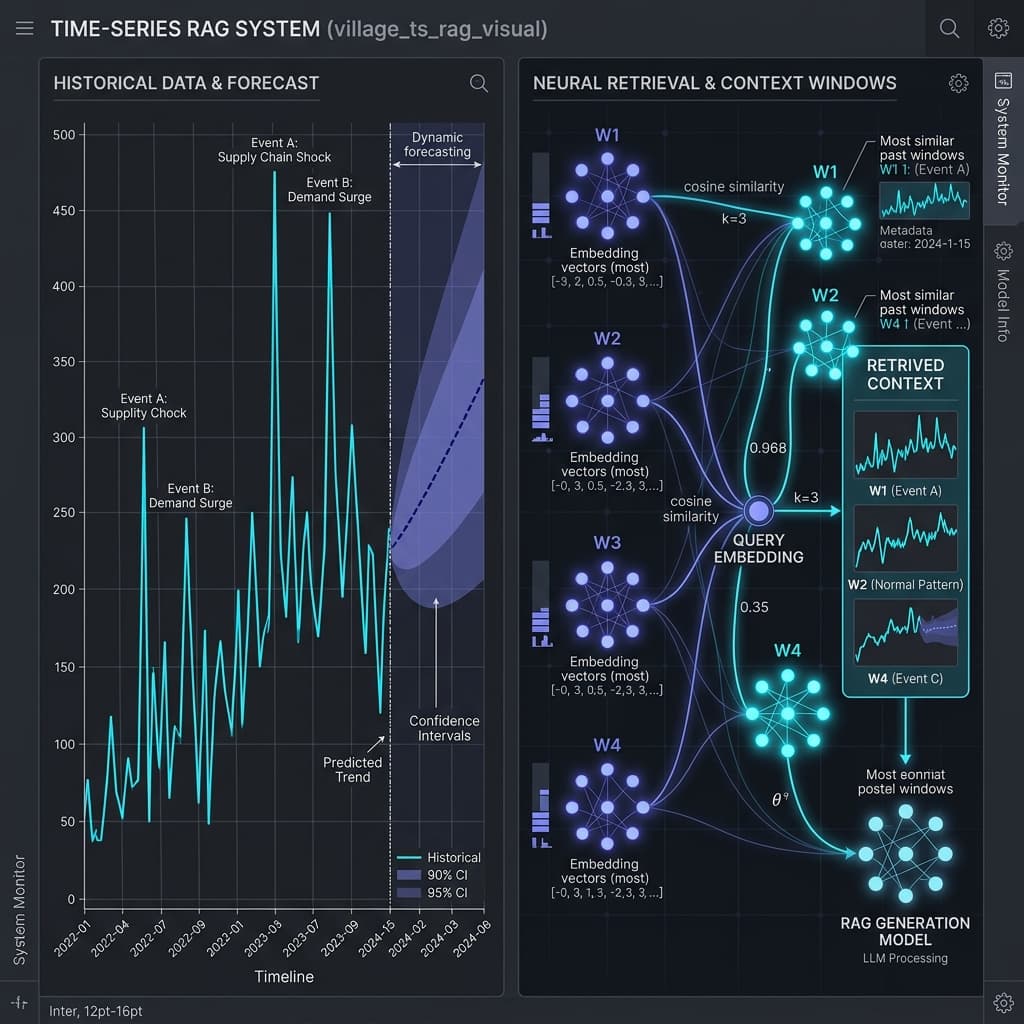
How to Build a Time-Series RAG for Forecasting Data
Standard RAG is for text; Time-Series RAG is for numbers. Learn how to combine LLMs with historical patterns, statistical insights, and LangGraph to build more accurate forecasting systems.
Build Multi-Tenant RAG with Pinecone and Next.js (2026)
Chat with your PDFs per workspace: chunk, embed and upsert into Pinecone namespaces, retrieve context, and stream answers from a Next.js app.
Getting Started with LangChain in 2026: Build a RAG Agent and a RAG Chain
Build retrieval-augmented generation two ways with LangChain 1.x: an agent that calls a retrieval tool, and a chain that injects context every time.
News & Analysis
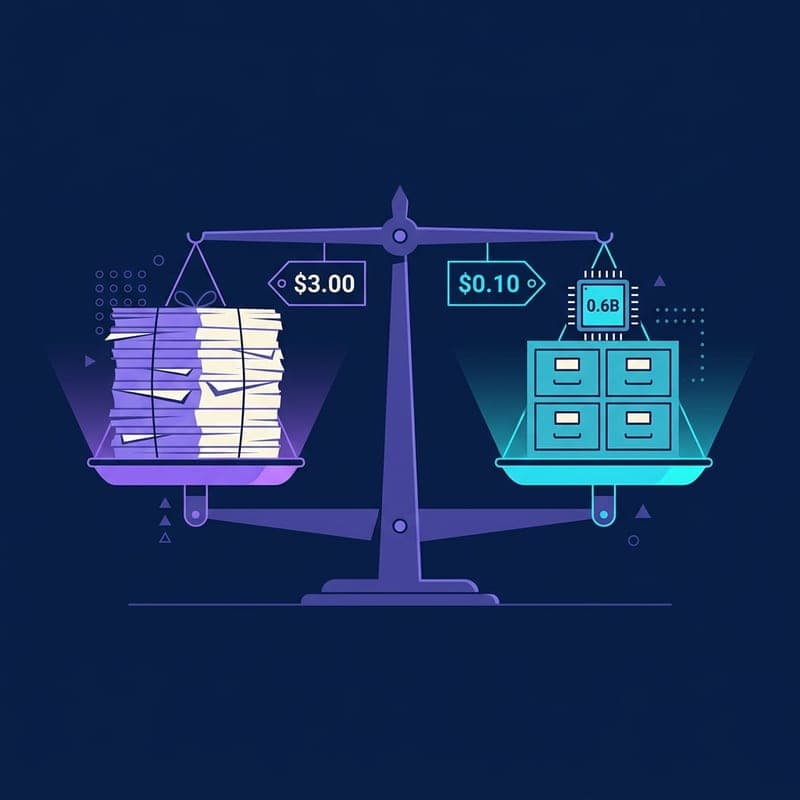
1M Context Is Now a Pricing Problem, Not a Capability Race
At $0.10–$3.00 per million input tokens, 1M context makes whole-document vs retrieval an arithmetic choice, not a capability race.
Perplexity's 9B Contextual Embedder Beats voyage-context-4 by 14.4 Points
Perplexity releases pplx-embed-v2-context-9b-preview, an open-weights 9B RAG embedder that scores 45.5% Answer Recall@10 and cuts storage 8× vs float32.
Production AI Fails on Architecture, Not Model Intelligence
Enterprise AI deployments stall because the harness breaks, not the model. Three failure modes prove why domain-specific architecture beats scaling.
Amazon Textract Preprocessing Fixes RAG Failures on Complex Documents
AWS shows how interposing Amazon Textract before a Bedrock Knowledge Base eliminates hallucination and incomplete extraction on PDFs, spreadsheets, and images.
Cohere Parse 5: 2.3B-Parameter VLM Beats Gemini 3 Flash on ParseBench
Cohere's Parse 5 scores 79.2 on ParseBench, outperforming Mistral OCR and Gemini 3 Flash with a 2.3B-parameter VLM that outputs Markdown plus bounding boxes.
NEEDLE Benchmark Rebuilds Search Queries Every Hour to Block Label Leakage
Keenable AI's MIT-licensed NEEDLE benchmark regenerates web search queries from live public sources, eliminating the fixed answer keys agents can fetch or memorize.
Cloudflare AI Search Bundles Full RAG Pipeline in One CLI Command
Cloudflare AI Search wraps crawling, embedding, vector storage, and ranking into one managed service with a single wrangler command and free beta access.
Six Cheaper Rungs Under RAG: When Not to Reach for the LLM
Kezhan Shi maps six deterministic methods that settle most enterprise document requests faster and cheaper than an LLM call—with a full audit trail.
Sentence Transformers v6.0 Adds ColBERT Training in 14.5 Hours on One GPU
Sentence Transformers v6.0 adds MultiVectorEncoder with full ColBERT-style training. A single RTX 3090 run beats every zero-shot retriever by 0.06 NDCG@10.
Row-Level RAG Chunks Cut Table Context by 7.7x
Serialising each table row as its own chunk returns 122 chars instead of 943 on a targeted lookup — a 7.7x context reduction with no parser changes.
AWS Cuts RAG Token Costs 33% With a Two-Call Compression Pattern
A post-retrieval Lambda function routes chunks through Claude Haiku before Claude Sonnet, cutting tokens by 8.6× and costs by 33% across 500K documents.
FBG Multi-Agent Support System Cuts Containment Gap 56%
Fanatics Betting and Gaming's AWS multi-agent system improved containment 56% and resolution 53% in two months, using Claude, Nova Lite, and custom RAG.
Kimi K3's 1M-Token Window Costs 16× More Than RAG on 12 Questions
A controlled 12-question blind trial pits Kimi K3's full 127K-token prompt against a tuned RAG pipeline. Long-context wins on completeness, loses on cost and latency.
LLM Judges Carry Nine Measurable Biases: What to Do
DHS 2026 research catalogues nine exploitable biases in LLM-as-judge pipelines and shows grounded evaluators as the structural fix.
Nine Measurable Biases That Corrupt LLM Judge Verdicts
A DHS 2026 workshop catalogued nine distinct biases in LLM-as-judge pipelines — and showed grounded evaluation as the structural fix.
Harness-1 Shows Smaller Open Models Can Beat Frontier AI at Search
Harness-1 is a 20B open-source search agent that beats GPT-5.4 on recall by moving search memory out of the model and into a structured environment.
Why AI Agents Need a Terminal, Not Just a Vector Database
Researchers propose Direct Corpus Interaction (DCI) — a technique that gives AI agents raw bash-like terminal access to search corpora, outperforming dense retrievers by over 30 points on multi-hop QA while cutting costs by 29%.
Why Vector Databases are Essential for Enterprise AI
A deep dive into embeddings, semantic search, and why standard SQL databases aren't enough for LLM context retrieval.
The Economics of RAG vs. Fine-Tuning in Enterprise AI
A deep dive into architecture strategy: When should your company use Retrieval-Augmented Generation, and when is it worth paying for Fine-Tuning?