
Ollama
13 pieces on Ollama, including 11 step-by-step guides.
Guides
Run an LLM Locally to Interact with Your Documents: Complete Ollama & Open WebUI Guide
Build a completely offline, zero-leakage local document intelligence system using Ollama, Open WebUI, and nomic-embed-text with custom chunking and system prompt engineering.
Run LLMs Locally: 6 Practical Methods (Ollama, LM Studio, vLLM, Jan, llama.cpp, and llamafile)
Master 6 proven frameworks to host and run LLMs locally across Windows, macOS, and Linux with GPU acceleration, from one-click GUIs to high-throughput production servers.
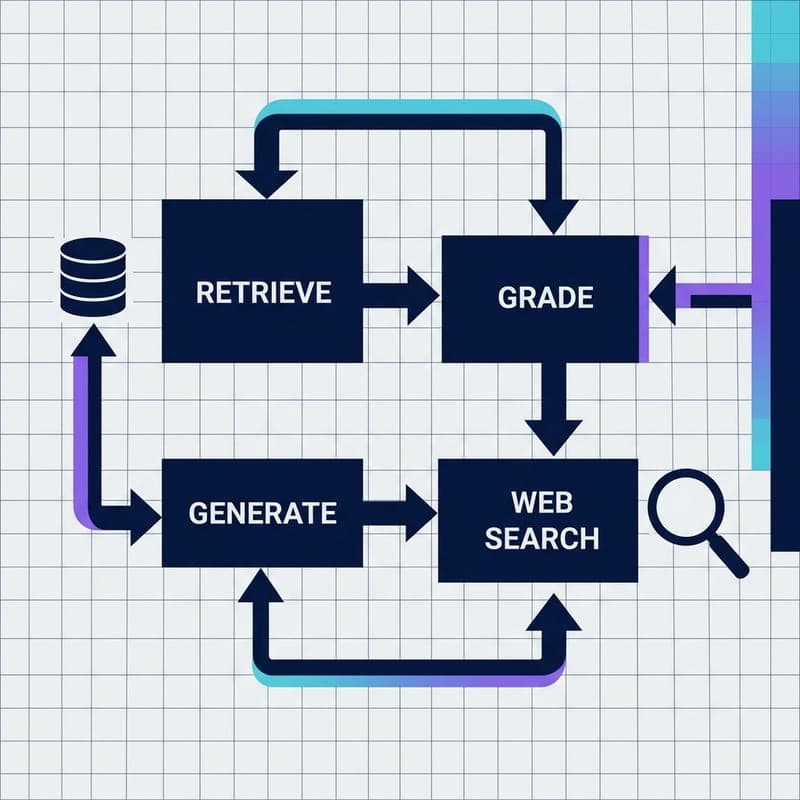
Build a Self-Correcting RAG Agent with LangGraph and Milvus
Wire adaptive routing, corrective RAG, and self-RAG into a stateful LangGraph agent backed by Milvus Lite — no OpenAI key required.
Build a Local LLM Zero-Shot Classifier You Can Actually Deploy
Learn how to run zero-shot text classification on a local model with Ollama, enforce strict JSON outputs, and add confidence-aware routing for production triage.
The Complete Developer Guide to Running LLMs Locally: From Ollama to Production
Everything you need to run LLMs on your own hardware in 2026: VRAM sizing, model formats, an 8-tool comparison table, a full local RAG pipeline, and Docker production deployment with GPU passthrough and Nginx auth.
How to Run DeepSeek R1 Locally with Ollama: Full Setup Guide
Install DeepSeek R1 locally using Ollama in under 5 minutes. Covers model variant selection from 1.5B to 671B, visible chain-of-thought reasoning, REST API usage, Python integration, and building a simple RAG application.
How to Run Qwen3 Locally with Ollama: Setup, API, and a Gradio App
Set up Qwen3 locally in minutes using Ollama. Covers every model variant, thinking mode control with /think and /no_think tags, CLI, REST API, Python SDK, and a practical Gradio reasoning app.
The Developer's Guide to Running Claude Code for Free: Ollama, OpenRouter, and Local Proxies
Stop paying for Anthropic tokens. Learn the engineering patterns required to redirect Claude Code's CLI to local models via Ollama or high-parameter free models on OpenRouter.
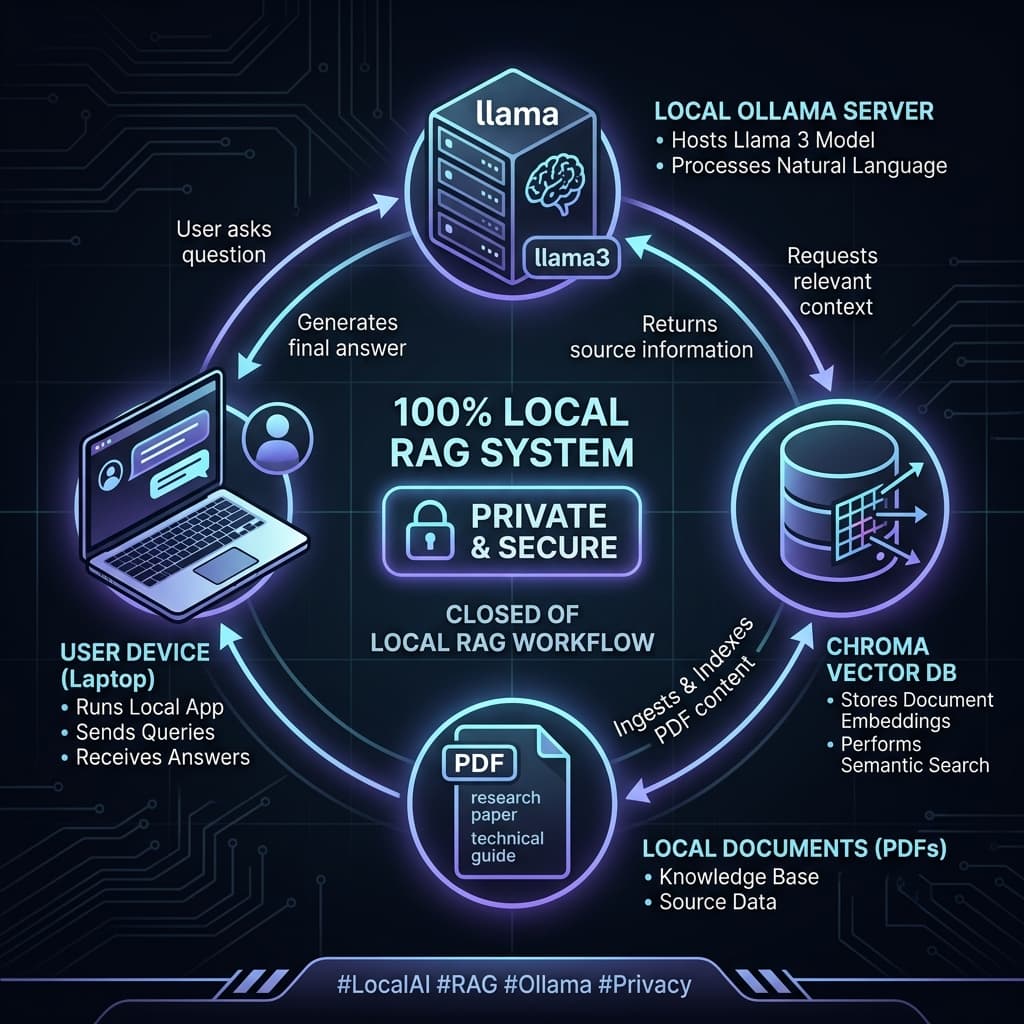
Local RAG Tutorial: LangChain, Ollama & ChromaDB with Ragas
Build a fully local, private RAG system using Ollama, ChromaDB, and LangChain. Includes a Python Streamlit app, a Node.js variant, and automated evaluation with Ragas.
Run Claude Code Locally with Ollama (2026 Setup)
Connect Claude Code to Ollama's Anthropic-compatible API, choose a supported coding model, set a 64K context, and verify inference stays local.
Build a Tool-Calling Agent with a Local Small Model and Ollama (2026)
Give a local small language model tools with Ollama's Python library: function tools, multi-tool streaming with thinking, and validated JSON output.
News & Analysis
Qwen3.8-27B Runs as a Local Coding Agent in 3 Commands
Ollama plus OpenCode collapses local Qwen3.8-27B setup to three terminal commands — no server config, no llama.cpp compilation.
Structured Output with Local LLMs: When Valid JSON Is Not Enough
Gemma 4's 4B model returns schema-valid JSON that still includes the wrong device. Here's the decomposition pattern that fixes it.