
Local LLMs
9 pieces on Local LLMs, including 7 step-by-step guides.
Guides
The Complete Developer Guide to Running LLMs Locally: From Ollama to Production
Everything you need to run LLMs on your own hardware in 2026: VRAM sizing, model formats, an 8-tool comparison table, a full local RAG pipeline, and Docker production deployment with GPU passthrough and Nginx auth.
How to Run DeepSeek R1 Locally with Ollama: Full Setup Guide
Install DeepSeek R1 locally using Ollama in under 5 minutes. Covers model variant selection from 1.5B to 671B, visible chain-of-thought reasoning, REST API usage, Python integration, and building a simple RAG application.
Run DeepSeek V4 Flash Locally with llama.cpp (2026)
Run DeepSeek V4 Flash locally with llama.cpp, a GGUF build, one 96GB GPU, and explicit checks for the current experimental support path.
How to Run Qwen3 Locally with Ollama: Setup, API, and a Gradio App
Set up Qwen3 locally in minutes using Ollama. Covers every model variant, thinking mode control with /think and /no_think tags, CLI, REST API, Python SDK, and a practical Gradio reasoning app.
Self-Host DeepSeek V4 with vLLM: 2026 Deployment Guide
Deploy DeepSeek V4 Flash or Pro with vLLM, size the GPU cluster, configure tensor parallelism, and compare self-hosting with current API prices.
Run Claude Code Locally with Ollama (2026 Setup)
Connect Claude Code to Ollama's Anthropic-compatible API, choose a supported coding model, set a 64K context, and verify inference stays local.
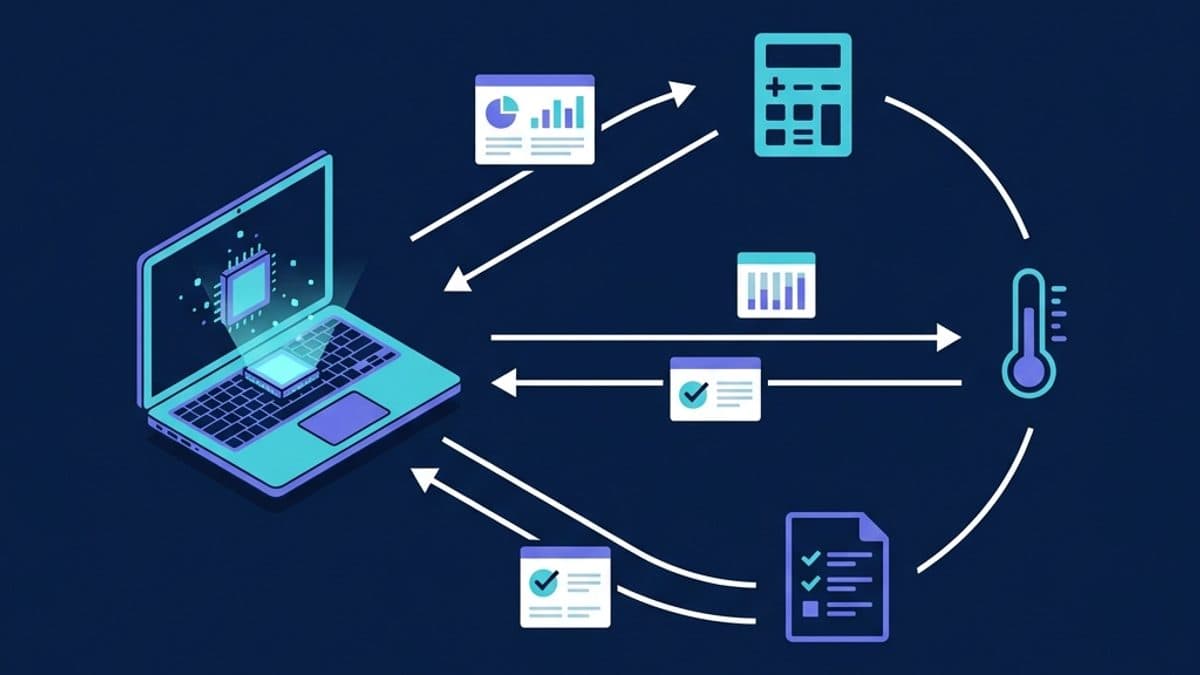
Build a Tool-Calling Agent with a Local Small Model and Ollama (2026)
Give a local small language model tools with Ollama's Python library: function tools, multi-tool streaming with thinking, and validated JSON output.
News & Analysis
Qwen 3.8 27B Is Capable but Defaults to Extreme Overthinking
Alibaba's Apache 2.0-licensed 27B vision model fits in 17 GB and handles agents, vision, and code — but its xhigh reasoning default is a trap.
Structured Output with Local LLMs: When Valid JSON Is Not Enough
Gemma 4's 4B model returns schema-valid JSON that still includes the wrong device. Here's the decomposition pattern that fixes it.