llama.cpp
8 pieces on llama.cpp, including 7 step-by-step guides.
Guides
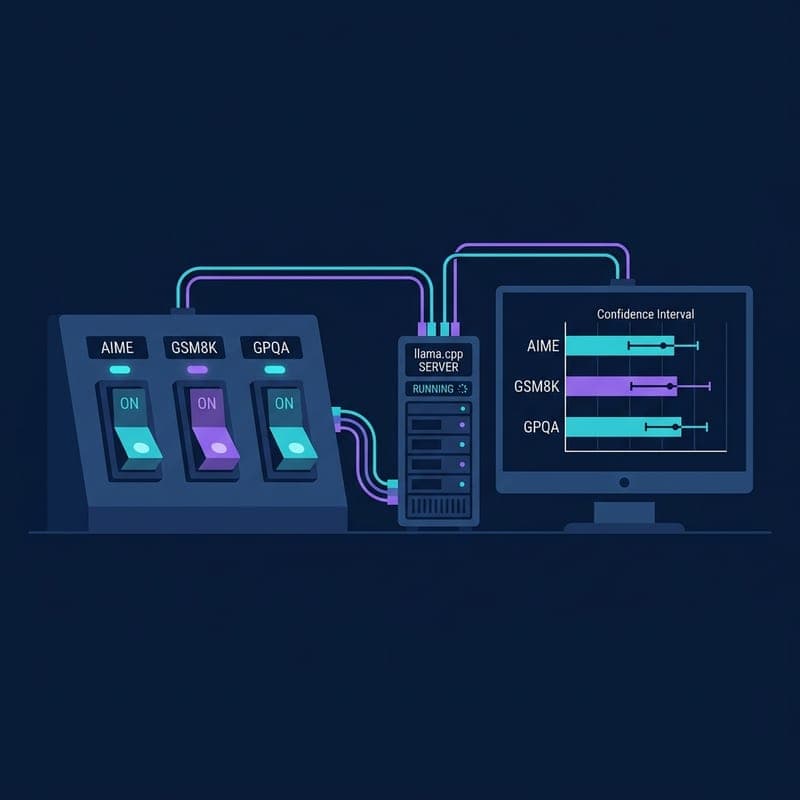
Benchmark Local Models with llama.cpp's llama-eval.py
Use llama.cpp's single-file eval harness to run reproducible AIME, GSM8K, and GPQA benchmarks against a local server with Wilson confidence intervals.
Run LLMs Locally: 6 Practical Methods (Ollama, LM Studio, vLLM, Jan, llama.cpp, and llamafile)
Master 6 proven frameworks to host and run LLMs locally across Windows, macOS, and Linux with GPU acceleration, from one-click GUIs to high-throughput production servers.
Host and Run Qwen3.8-Flash Locally: Complete Unsloth and llama.cpp Deployment Guide
Run Qwen3.8-Flash locally on CPU, unified memory, or GPUs using Unsloth and llama.cpp with Multi-Token Prediction (MTP) for up to 1.7x faster inference.
Fine-Tuning LLMs with LoRA: A Complete Practical Guide to Training & GGUF Deployment
Master end-to-end LoRA fine-tuning for SLMs: synthetic data generation, benchmarking against 7B baselines, lit-gpt training, and GGUF serving with llama.cpp.
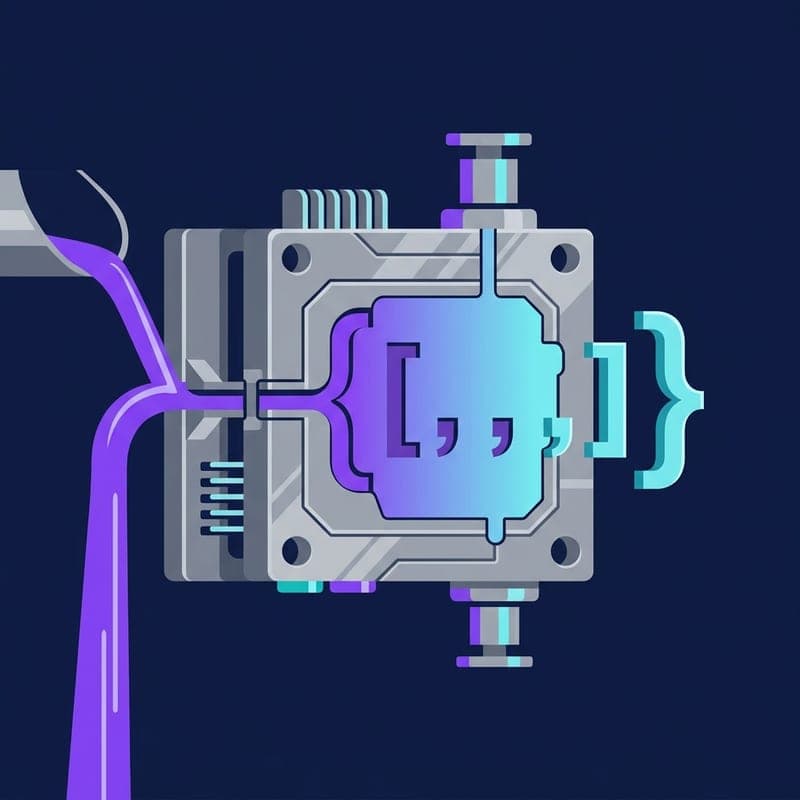
Guaranteed JSON from llama.cpp with Pydantic and GBNF grammars
Use llama.cpp's GBNF grammar constraints and Pydantic validation together to make invalid JSON structurally impossible at inference time.
The Complete Developer Guide to Running LLMs Locally: From Ollama to Production
Everything you need to run LLMs on your own hardware in 2026: VRAM sizing, model formats, an 8-tool comparison table, a full local RAG pipeline, and Docker production deployment with GPU passthrough and Nginx auth.
Run DeepSeek V4 Flash Locally with llama.cpp (2026)
Run DeepSeek V4 Flash locally with llama.cpp, a GGUF build, one 96GB GPU, and explicit checks for the current experimental support path.